Issues / #3110
#3110 vhotseat: Strata and ComfyUI take turns on one GPU, so a local agent can render video on the same card it runs on
open · @wandermyz · 0 コメント · GitHub で見る
Setup & installAMD / HIPNVIDIA / CUDAModels & quantsDocumentationWindowsLinux
本文
vhotseat is a small tool that runs next to Strata and ComfyUI on the same PC. It makes them take turns on VRAM *and* RAM, so a local agent served by Strata can queue image and video renders on the card it runs on, with no out-of-memory errors. ComfyUI is just the example: any other GPU job (a training run, a simulation, a script) can take turns with Strata the same way by running it as `vhotseat hold NAME -- COMMAND`. Linux and NVIDIA, Python 3.10+, one dependency (PyYAML), MIT: https://github.com/wandermyz/vhotseat **The problem.** On a 16 GB card, Strata holds ~14.7 GB of VRAM and ~44 GB of RAM for Flash-Next IQ3_XXS, and a MiniMax H3 video render needs ~14 GB of VRAM. When the agent queues a render, one of them runs out of memory. **How it uses Strata.** Strata's `before_load` hook runs `vhotseat gate strata`. Strata's lazy load and idle unload do the rest: - **The agent queues a render.** A small custom node in ComfyUI runs `vhotseat switch comfy` before every job. It waits for any answer Strata is writing, then unloads Strata. - **The agent asks its next question.** Strata's `before_load` hook asks vhotseat first. While ComfyUI still has jobs queued or running, it refuses, and the agent's harness retries the 503. Once ComfyUI is idle, vhotseat frees its models (and restarts it if its leftover RAM is in the way), then lets Strata load. - **Running work is never interrupted.** That covers an answer Strata is writing and a render in progress. Nothing else is changed in Strata: only the `before_load` key in the run config. Any client is covered (the agent, its scripts, the ComfyUI web page, curl), because nobody calls vhotseat; each side asks for the GPU right before it loads. ## Demo Setup: RTX 5070 Ti 16 GB, 64 GB RAM, Linux. Strata serving Qwen3.8-Flash-Next IQ3_XXS at 128K context, [pi](https://github.com/earendil-works/pi) as the agent, MiniMax H3 (int8 `fl2va`) in ComfyUI. The prompt to pi: > Make two 3-second anime-style clips of a cat on a windowsill with MiniMax H3, then tell which one looks better. Continue working on a clip of the cat jump from windowsill to catch a bird. Concat this two clips into a single video file. pi did it unattended, in two render rounds. 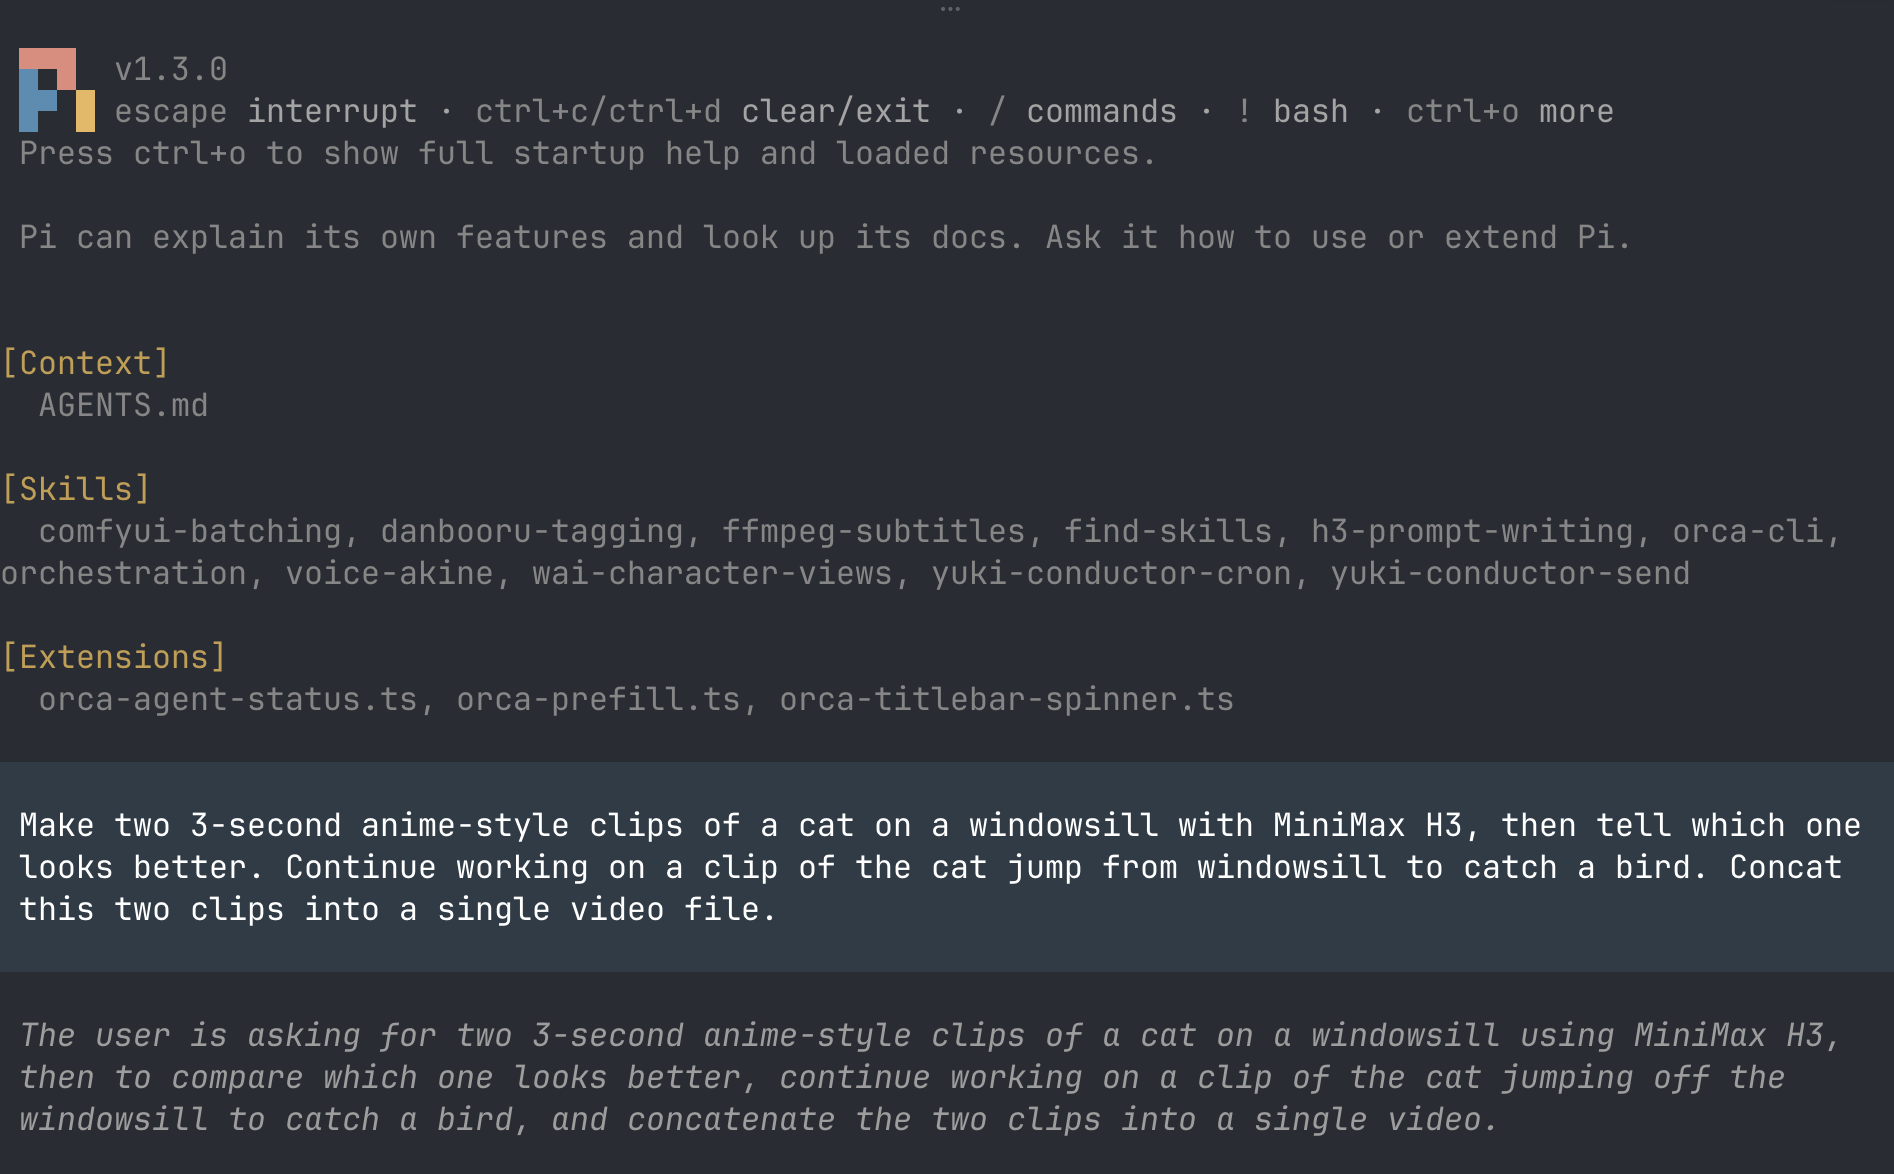 **Round 1.** pi wrote the job files and rendered two takes (two seeds) in one batch, which took 3 min 41 s. Strata was unloaded for the batch. 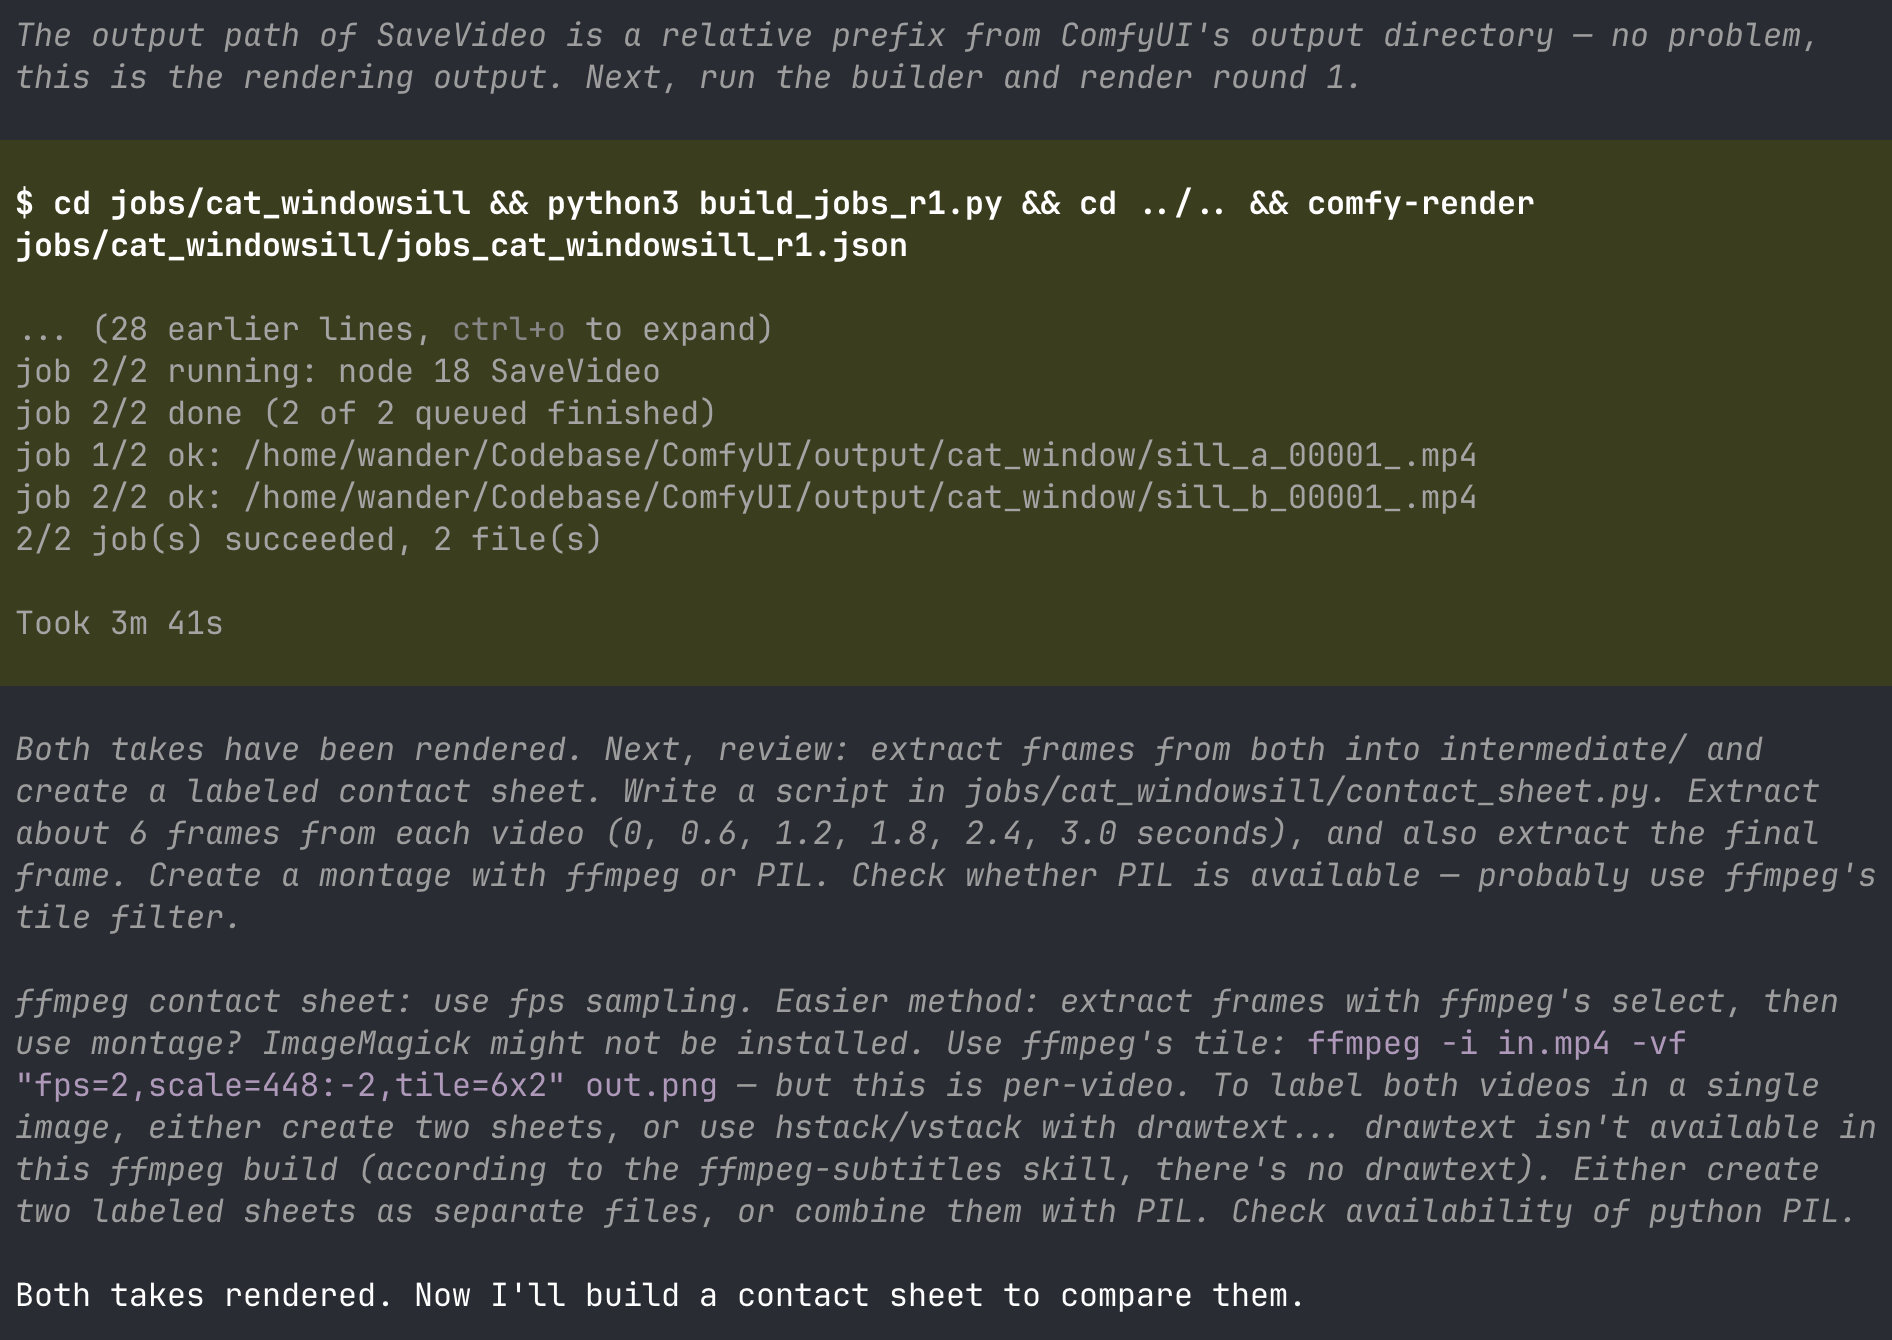 **Review.** Strata loaded again. pi built a contact sheet of both takes, looked at it with Flash-Next's vision, and picked take A, because "B substitutes a butterfly for the bird". 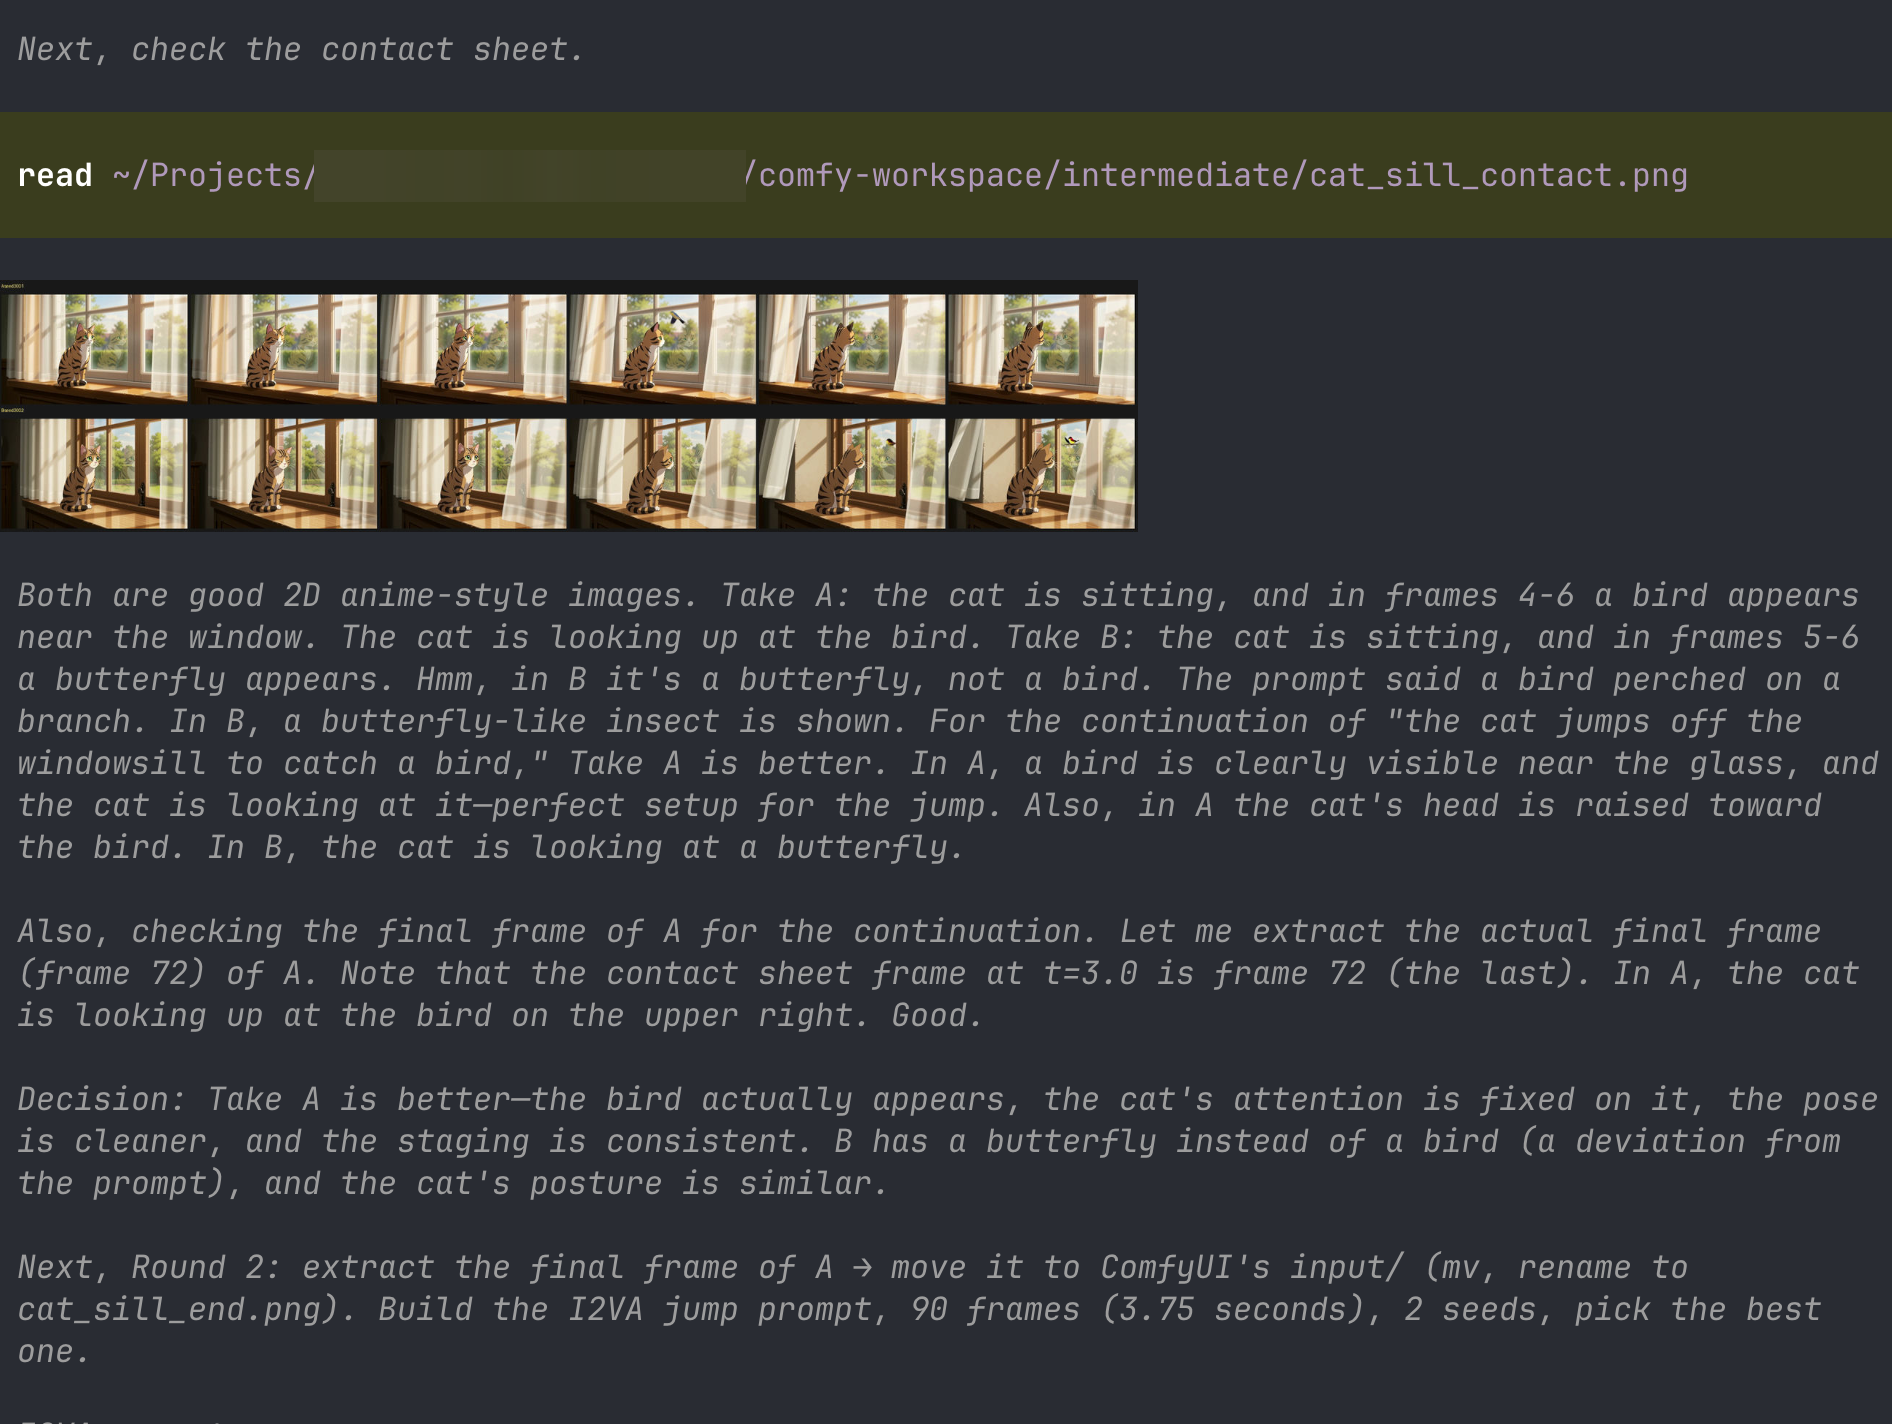 **Round 2.** pi took the last frame of take A as the first frame of the jump and rendered two takes, which took 5 min 38 s. 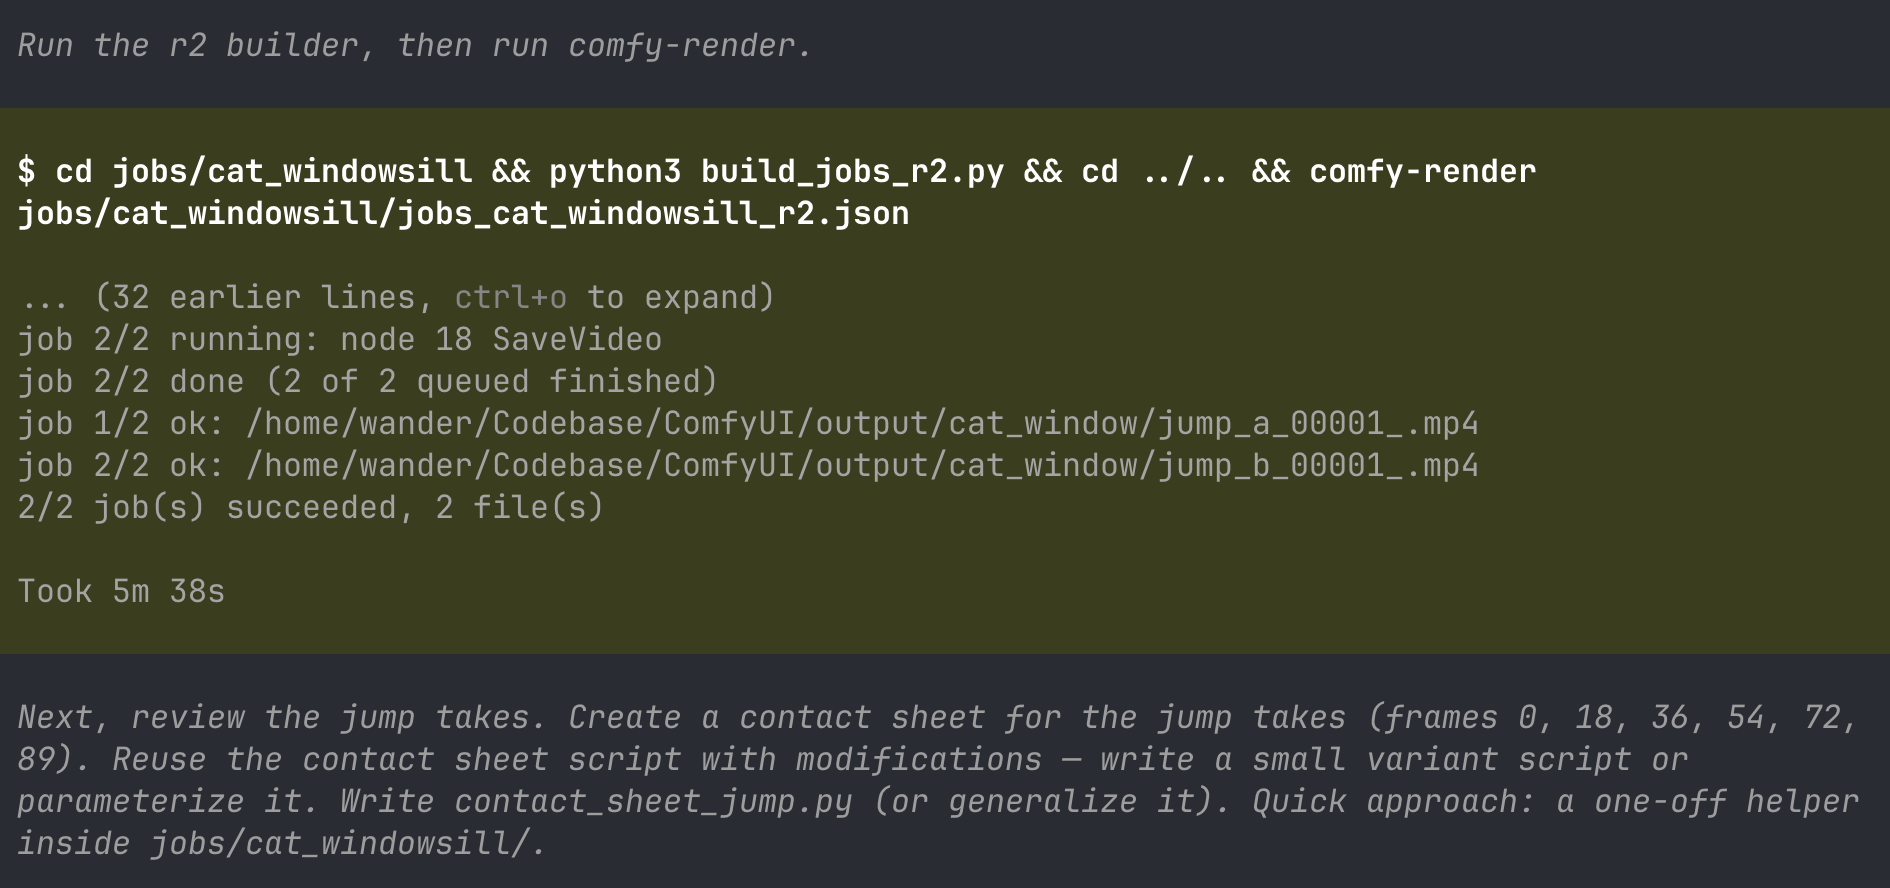 **Review and finish.** Strata loaded again. pi picked the take with a real leap, then joined the two clips with ffmpeg. 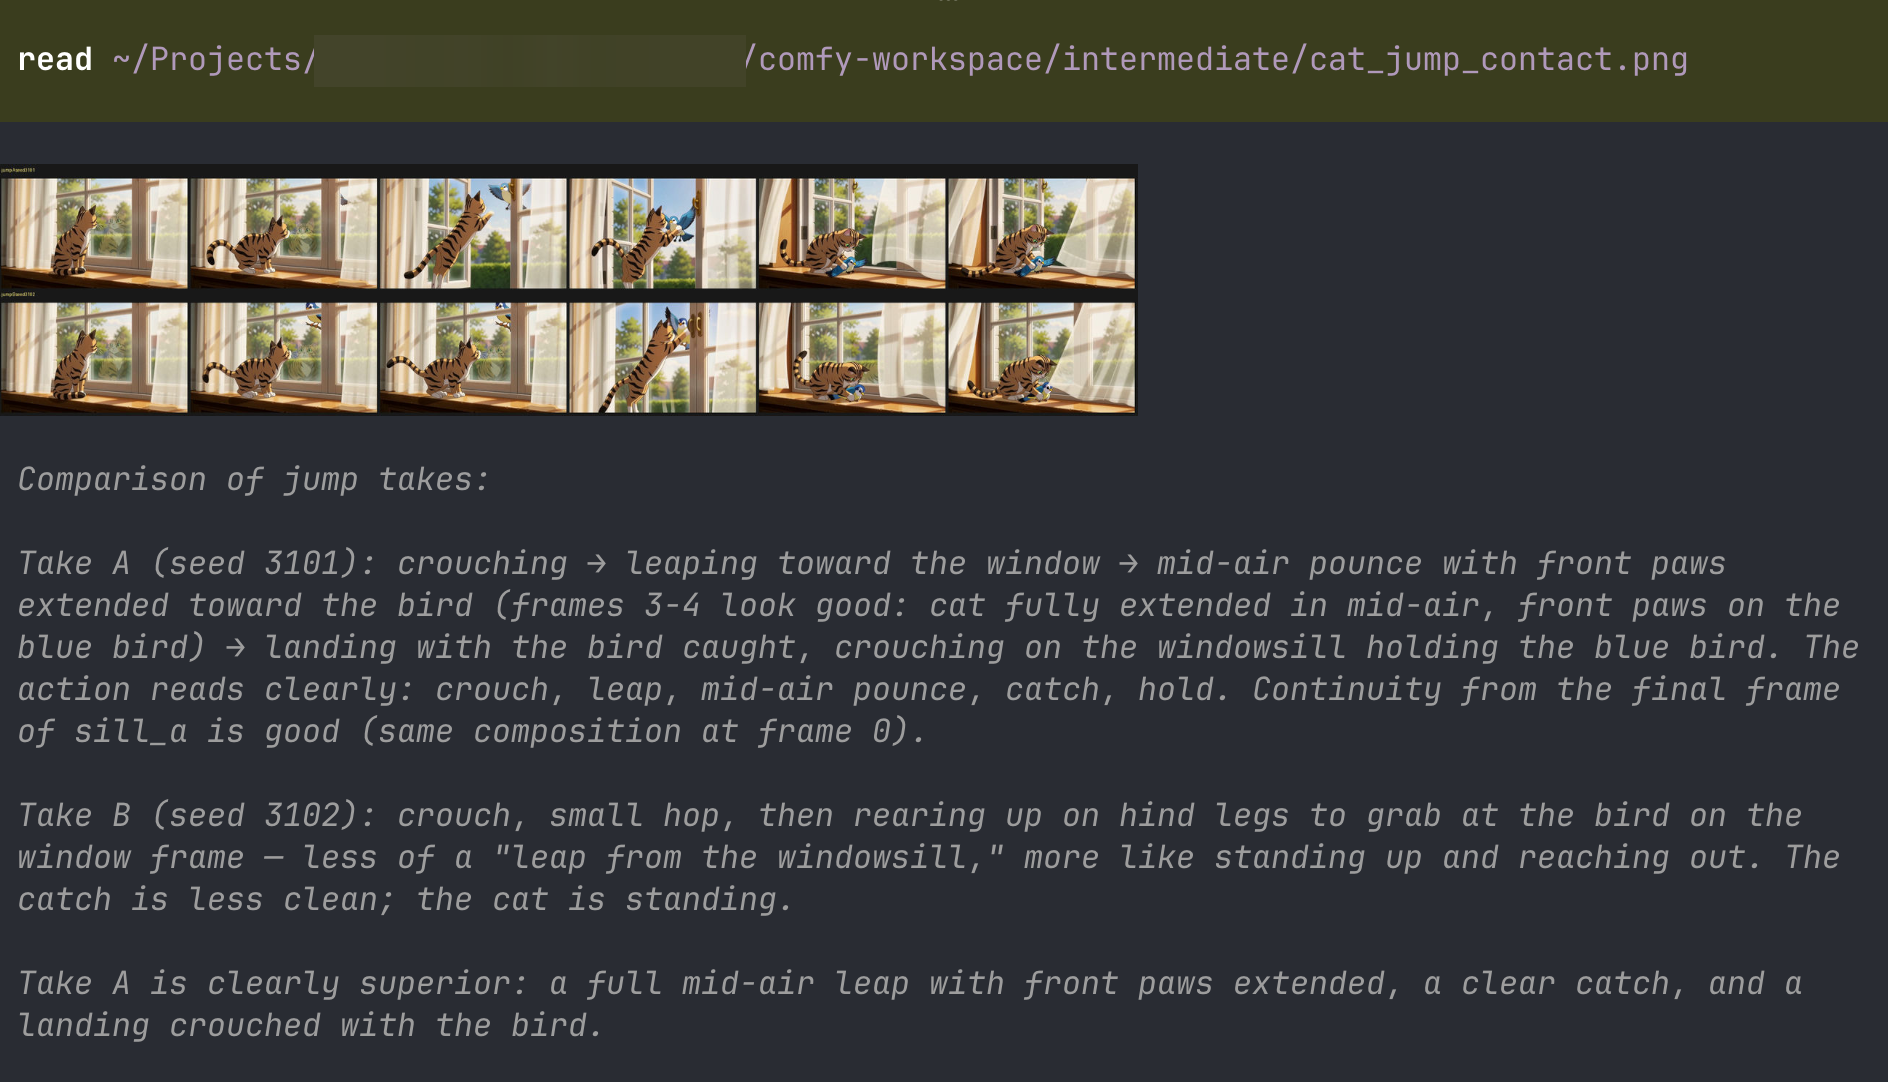 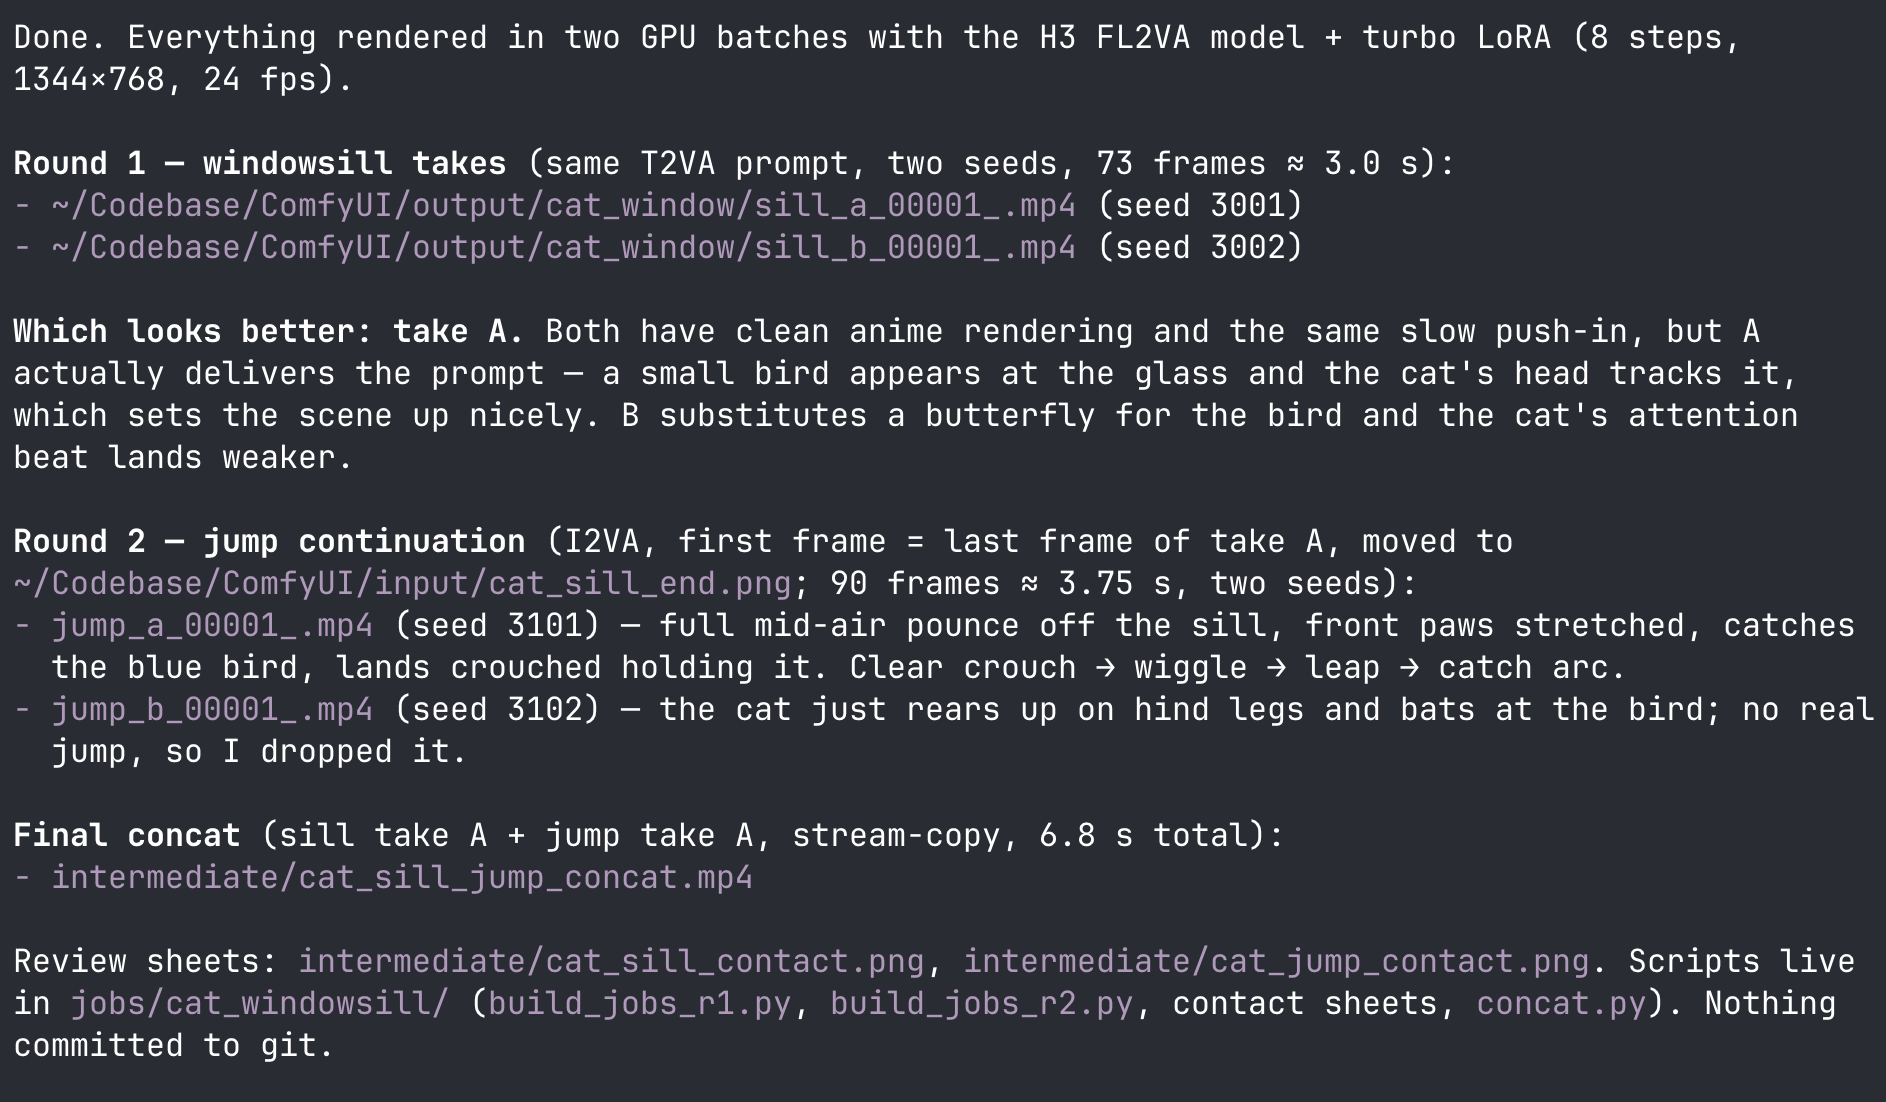 That's four GPU handovers, and no OOM. The final video (6.8 s, 1344×768): https://github.com/user-attachments/assets/4dc4e40d-caa6-4433-b654-718713c981cd `vhotseat web` shows the same session. The GPU goes to ComfyUI at 02:10 and 02:16, and comes back to Strata at 02:14 and 02:21. Each time Strata loaded, vhotseat freed ComfyUI's 13.9 GB of models first. Strata's RAM goes from ~44 GB down to almost nothing while ComfyUI renders, then back. 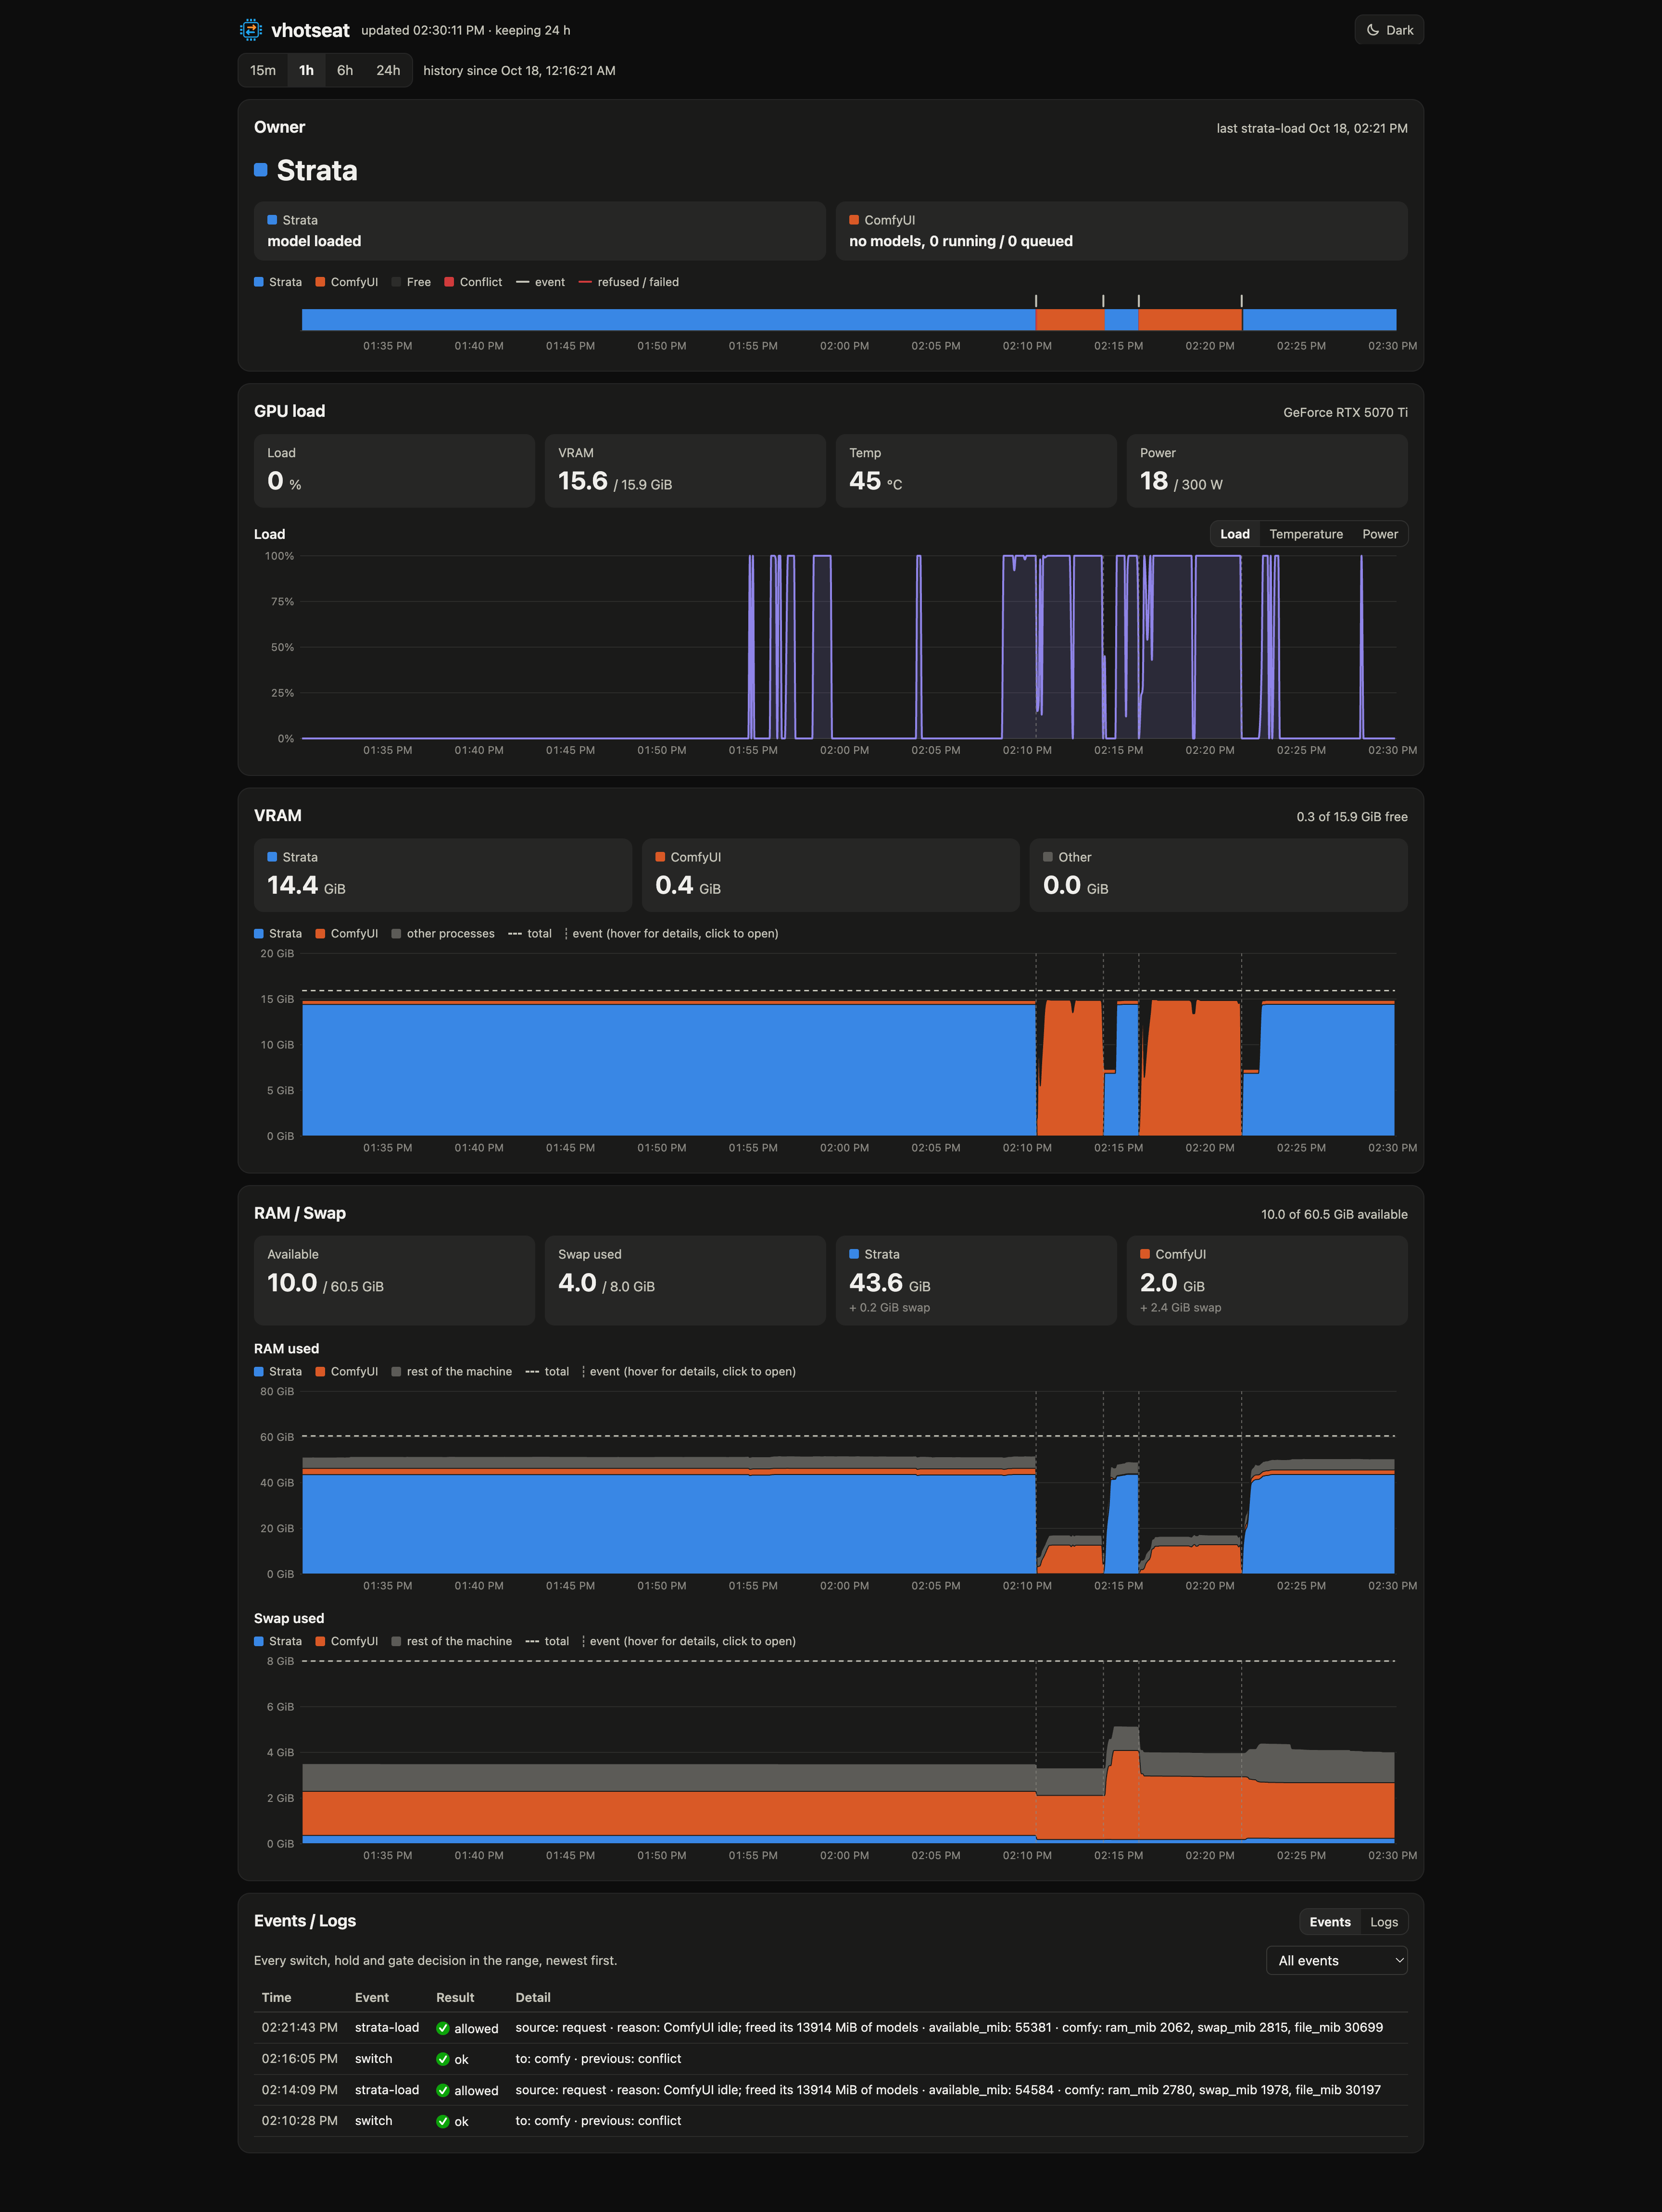 ## Try it ```sh uv tool install vhotseat # or: pipx install vhotseat ``` Or give this sentence to a coding agent on the PC where Strata runs: > Set up vhotseat so my local LLM agent can drive ComfyUI on this GPU without running out of memory. Follow https://github.com/wandermyz/vhotseat/blob/main/docs/guides/quickstart-strata-pi-comfyui.md, adapting it to the servers and paths on this machine, and run each step's check before going on. `vhotseat doctor` checks the config, the GPU and both gates; `vhotseat status` shows who holds the GPU. It writes only to Strata's run config (the `before_load` key) and its own config. The ComfyUI side is one custom node. Not tested: Windows (designed for, not done yet), AMD, Intel and Macs. Other servers (another LLM server, a TTS server, a training run) can join through a config entry or a small driver. Feedback is welcome here or in the vhotseat repository, especially reports from other cards and setups.
関連リンク
インストール・モデル・リリースへの站内リンク。