改动 / #3416
#3416 [Engine] Preserve target probabilities in gated MTP
open · @KeyanHu-git · 0 评论 · 去 GitHub 看
BenchmarksSetup & installServer & APIAMD / HIPNVIDIA / CUDAModels & quantsWindows
说明
## Problem and result
With `STRATA_SPEC_PROB=1`, the confidence gate selects drafts using the probability of the token it just drew. The original verifier still uses the unfiltered q, and a failed gate becomes a plain target sample. This biases the output toward the draft head's preferred tokens.
This patch keeps the confidence gate and accounts for the missing proposal mass explicitly. It also keeps CPU expert arithmetic independent of how many tokens share a speculative window, so the verifier samples the singleton target distribution.
For `p=(0.5,0.5)`, `q=(0.875,0.125)` and threshold `0.5`, the original gate emits `(0.5625,0.4375)`; the repaired gate emits `(0.5,0.5)`.
## Related discussion
Refs #2028. Thanks to KarlGrier for the report and derivation. This continues #2591 on v0.2.1 (`90767252`, engine 0.1.46). Its intake check passed, but GitHub rejected reopening the closed PR; the intake bot requested a linked replacement in that case.
## Approach
The proposal packet retains q on admitted tokens without renormalizing it; call this measure μ. A failed draw becomes an explicit NULL row. Offered tokens use `min(1,p(D)/μ(D))`; rejection and NULL sample the normalized positive part of `p−μ`. A row with no attempted proposal remains an ordinary bonus sample.
```mermaid
flowchart LR
Q[Draft distribution q] --> G[Confidence gate + eligible suffix root]
G --> M[Retained measure μ + NULL mass]
M --> O[Offered token]
M --> N[NULL]
O --> A[Accept with min 1, p / μ]
O --> R[On rejection: sample positive p − μ]
N --> R
```
CLI and serial serve share the packet builder. Attempt counts and context limits are decided at the producer boundary. Suffix eligibility uses committed context and request-fixed policy statistics. CPU dispatch preserves singleton arithmetic while retaining shared weight decoding where it gives the same result.
The 0.2 port preserves Trellis/Hadamard handling, per-job expert layouts and cold-read batching. Both ready and cold-read job submissions carry the arithmetic mode. ARM builds retain their native singleton arithmetic rather than referencing x86 kernels. Default exact-match drafting remains the default; explicit `top` gating remains available.
## Validation
**Passed:**
- `gated_proposal_test`: 266 checks, including macOS ASAN/UBSAN.
- `spec_admission_test` and `STRATA_SPEC_PROB_GATE=top spec_admission_test top`: 900 Top cases and 2,700 μ-packet cases per configuration, with the original biased rule as a negative control.
- `HIP_VISIBLE_DEVICES=1 STRATA_OLD_SAMPLER=0 STRATA_SAMPLER_ONE_BLOCK=0 spec_proposal_parity`: 432 rows, zero mismatches against an independent CPU oracle on RX 7900 XTX.
- `native_arithmetic_parity`: 4,866,048 finite bitwise comparisons in each of eight Windows configurations, including Trellis formats and Hadamard-folded inputs.
- Full CUDA, HIP, SYCL and Metal engine builds pass. CUDA/GCC and SYCL/oneAPI each pass 13 CPU tests; Metal also passes `strata --version` (`0.1.46-metal`).
- Incremental 12-position comparison against the genuine 0.2.1 release: patched MTP matches both no-MTP singleton references at all 12 raw-logit rows. Original MTP matches 1/12; its token-12 distribution has TV **0.0361348** from the singleton reference. All 24 sampled decisions reconstruct from captured p, q and counters. Trace builds reproduce production outputs.
- The default-mode original/patched 12-token outputs match. After the ARM compile fix, the rebuilt HIP candidate repeats the MTP/singleton check: all 24 logit rows and all outputs match the earlier candidate; the final default-mode check and sampler/CPU suites pass again.
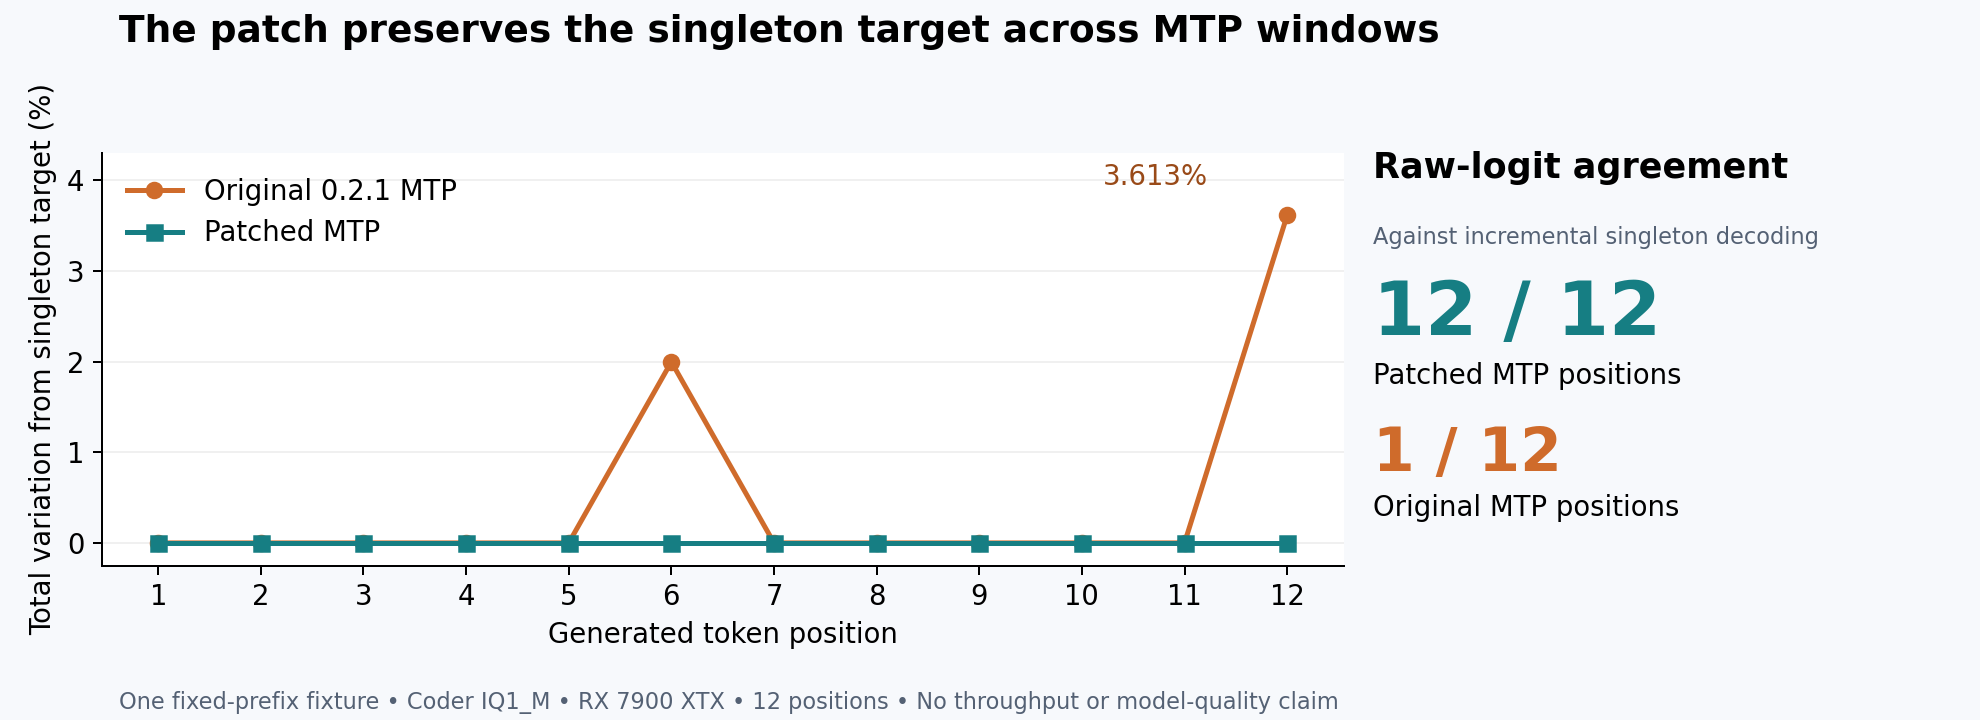
[Prompt, seeds, binary/library hashes, per-position distributions and figure source](https://github.com/KeyanHu-git/Strata/tree/470d558be39f1a8c8edda4d6058b8b5b8331035b/bench/results/2026-10-20-gated-mtp-v021). The six-run numerical probe generated 72 tokens in 115.47 seconds. Singleton controls advance one token at a time; they do not re-prefill the whole prefix.
**Failed:** No remaining failure in the checks listed above. During preparation, the Metal link exposed two x86-only references; architecture-specific dispatch fixes them. An initial GPU test selected the integrated GPU; the reported run explicitly selects the RX 7900 XTX. These failed setup attempts are retained in the local experiment record.
**Not run:** CUDA, SYCL and Metal model execution; a new full GSM8K evaluation; a 0.2.1 throughput benchmark.
## Limits
The repaired proposal path supports serial generation on one CUDA/HIP device, with lookup-chain, adaptive swaps and PCIe sharing off. Unsupported combinations report an error. SYCL and Metal compile but do not execute this proposal path.
The numerical fixture resolves the earlier token-12 target-probability discrepancy. It does not establish an aggregate model-quality score or explain the later long reasoning trajectory. The previous 100-pair speed measurements remain results for the older engine, not 0.2.1 performance claims.
本站相关内容
相关页面的快捷入口。