Pull requests / #1702
#1702 bench: validate 128K-1M live, RAM and disk cache reuse
open · @CC-David-CC · 0 コメント · GitHub で見る
BenchmarksMulti-GPUNVIDIA / CUDAModels & quantsDocumentation
本文
## Summary Validate #1667 checkpoint persistence with the existing RoPE/YaRN configurations covered by #1692. This integration branch includes those dependency commits; the new work is the benchmark harness, raw evidence and charts. Native inference code is unchanged; no cache converter is used. **At 1M, disk restore cuts first-token latency from 236.48s to 40.53s (5.8x). Including checkpoint writeback, the full request drops from 236.84s to 106.89s (2.2x faster; 130 seconds saved).** 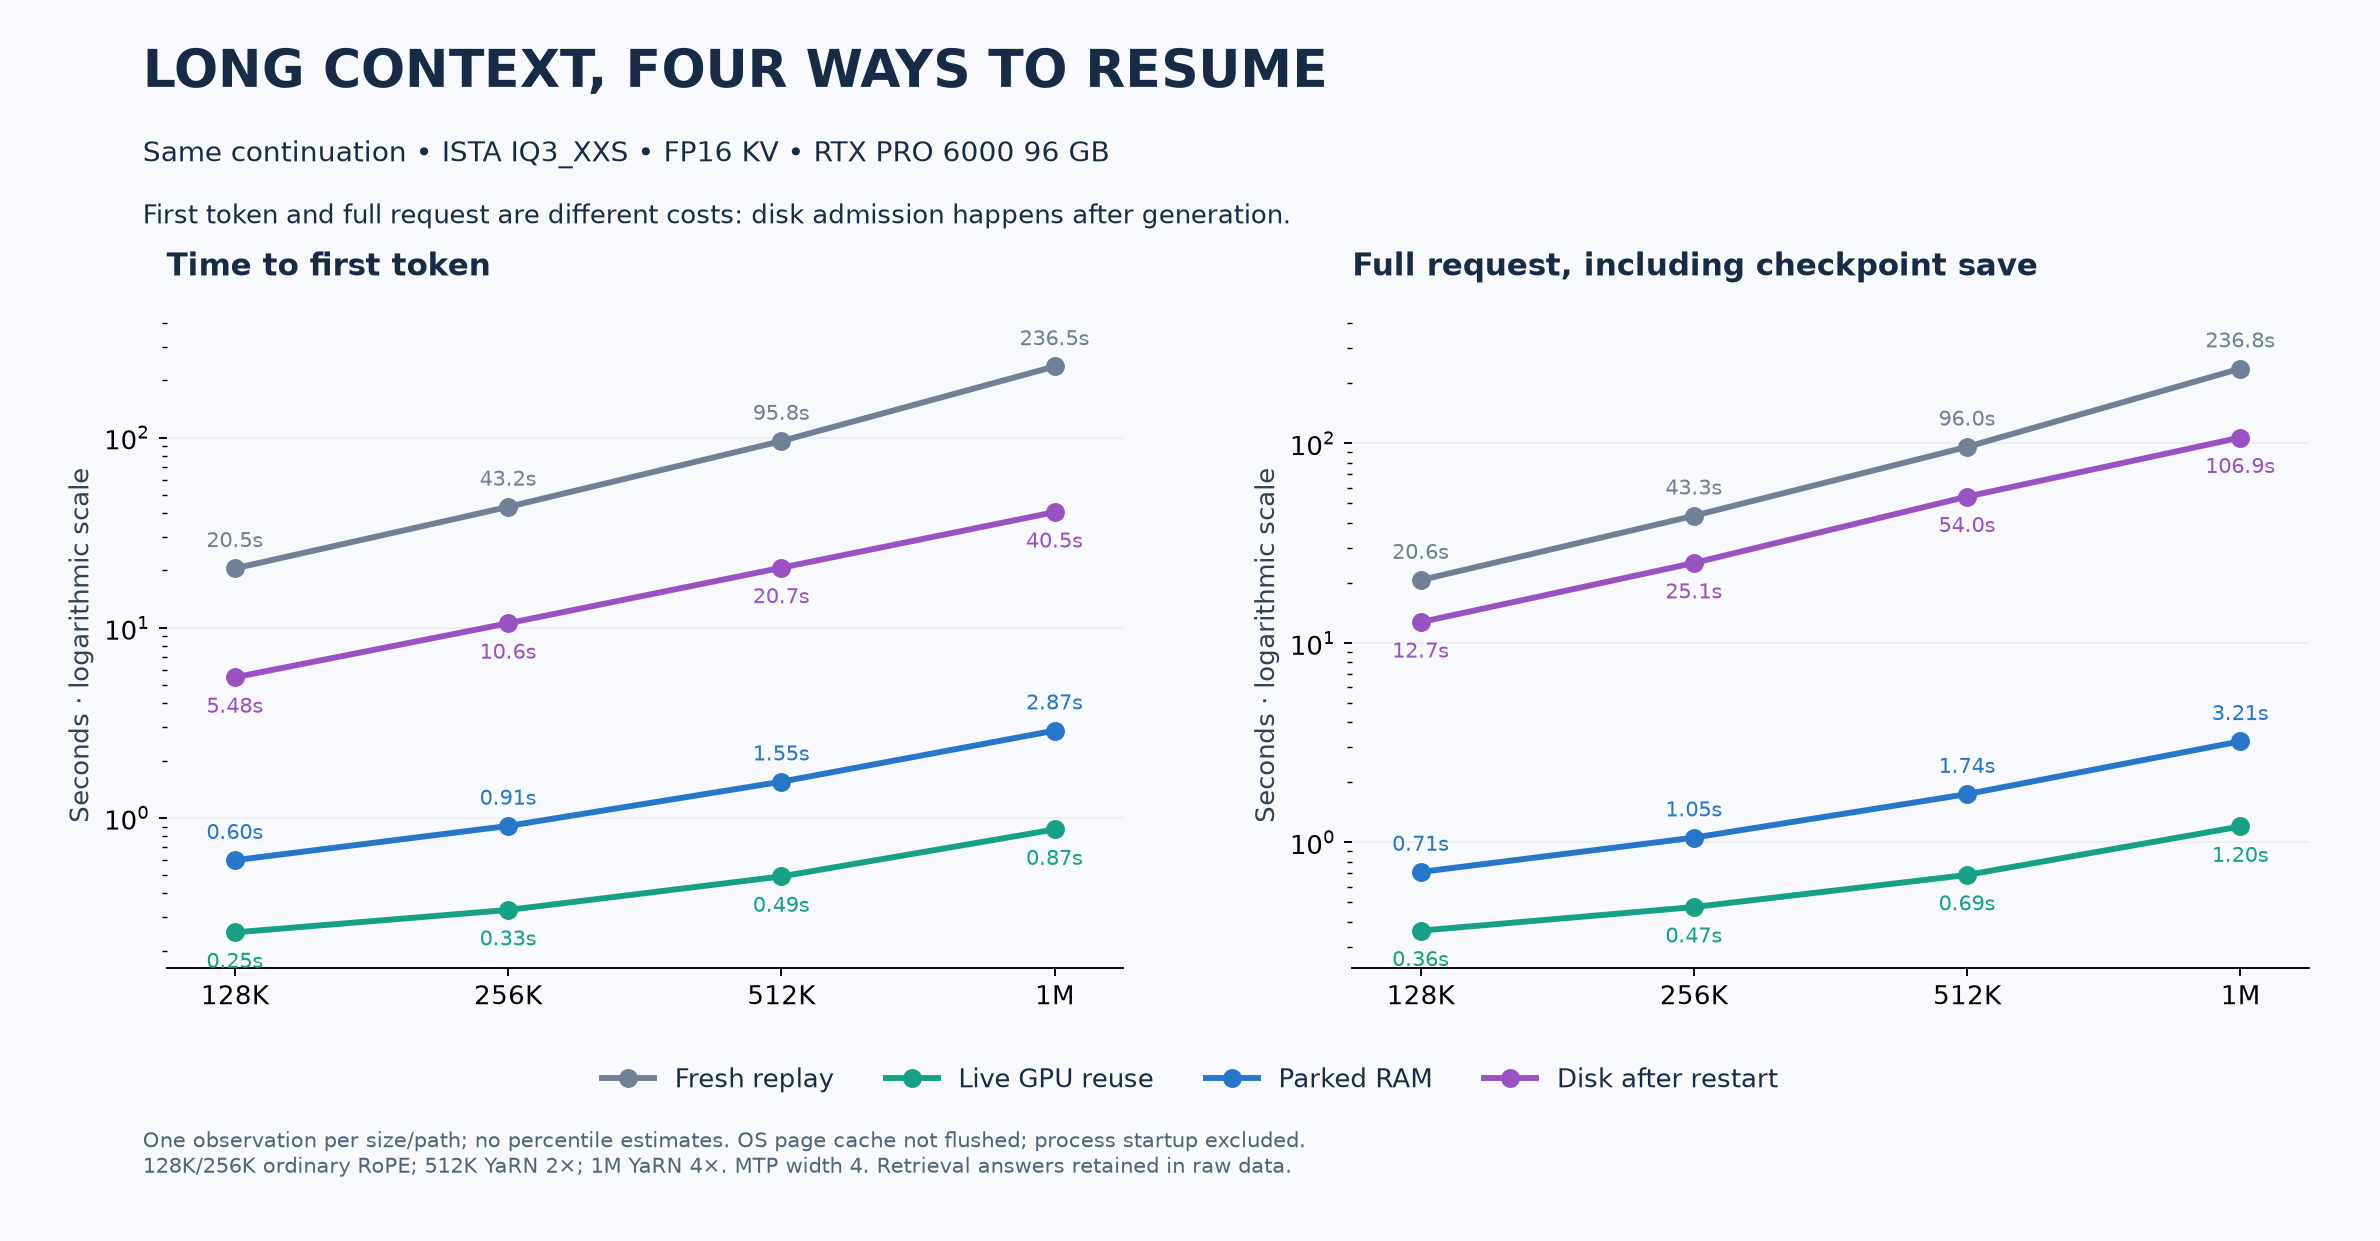 | Prefix | Fresh TTFT | Live | RAM restore | Disk restore | |---|---:|---:|---:|---:| | 128K | 20.51s | 0.25s | 0.60s | 5.48s | | 256K | 43.17s | 0.33s | 0.91s | 10.55s | | 512K | 95.78s | 0.49s | 1.55s | 20.67s | | 1M | 236.48s | 0.87s | 2.87s | 40.53s | 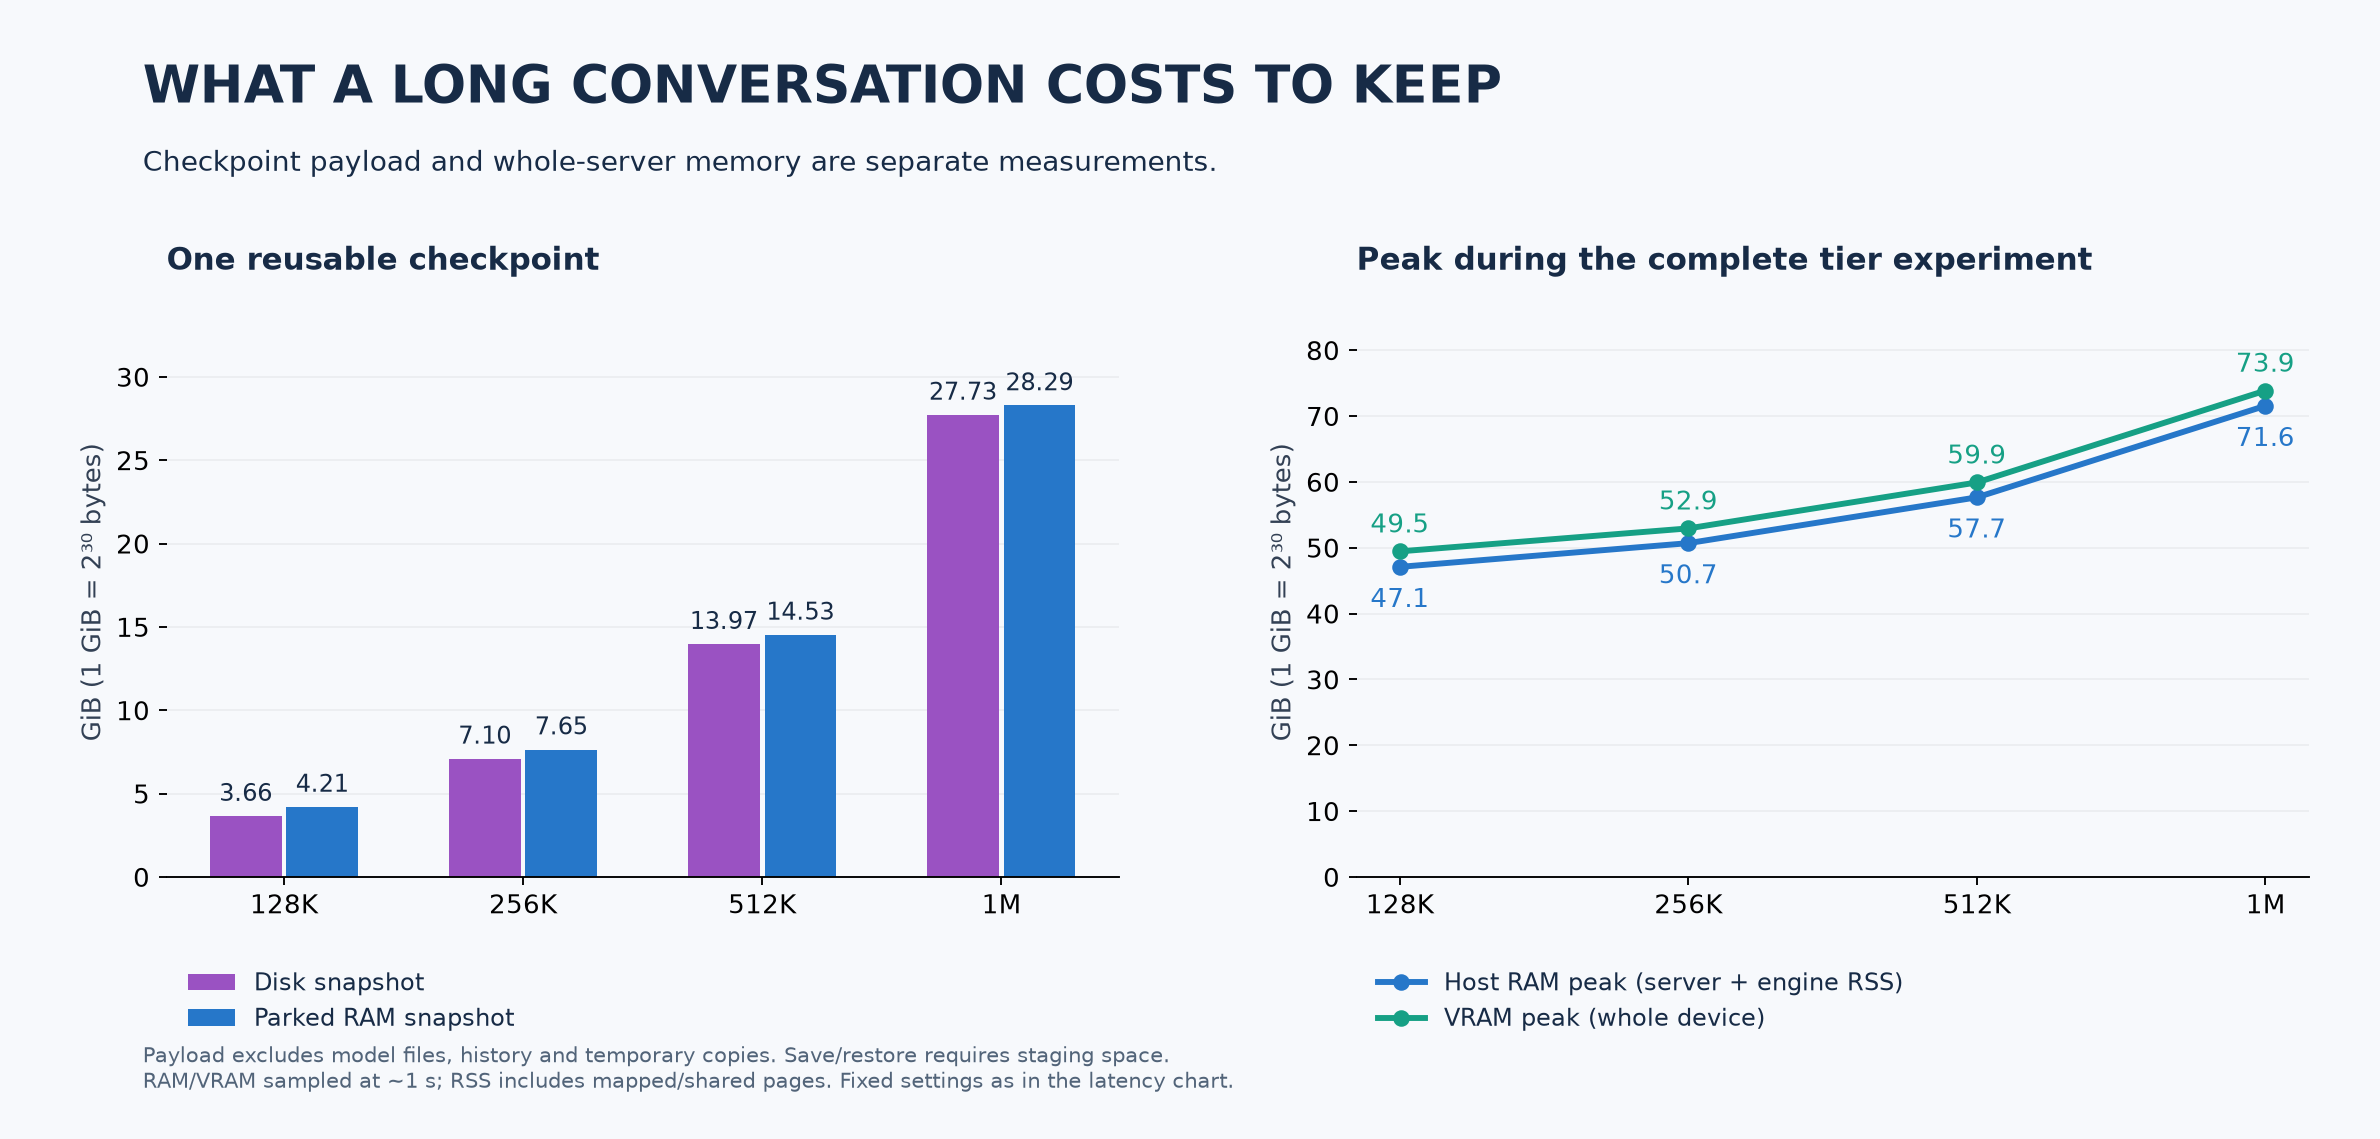 At 1M: 27.73 GiB disk checkpoint; 28.29 GiB parked RAM snapshot; peak server RAM 71.6 GiB, VRAM 73.9 GiB, temporary disk growth 83.3 GiB. Parking the outgoing 1M conversation itself costs 10.90s. ## Validation and reproduction RTX PRO 6000 96 GB; ISTA IQ3_XXS; FP16 KV; MTP width 4; 128-token output cap. Ordinary RoPE at 128K/256K, YaRN 2x at 512K and 4x at 1M. All 16 continuations recovered three codes placed near the beginning, middle and end. Example follow-up: "Return the three verification codes in order." Answer: `CEDAR-731 | MARBLE-482 | QUARTZ-956`. Identical continuation token hashes and execution identities across tiers; native RAM restores and bookmarked disk restores after restart verified. Focused regression tests: 56 passed, one optional SDK test skipped. One observation per condition, not percentile or general quality evidence. Startup excluded; OS page cache not flushed. RAM restore follows a tiny unrelated request, not a second equally large conversation. Cache tiers are isolated for comparison. [Commands, cache-budget settings, raw answers and measurements](https://github.com/CC-David-CC/Strata-a5500/blob/0bca799742343534dcf42ac714f29bc53a68f973/bench/results/2026-10-09-long-context-cache/README.md). The larger FP16 snapshots require raising the default 4 GiB snapshot limit.
関連リンク
インストール・モデル・リリースへの站内リンク。