Pull requests / #1171
#1171 docs: minor prefill config change results in faster prefill
closed · @CC-David-CC · 0 コメント · GitHub で見る
BenchmarksNVIDIA / CUDADocumentation
本文
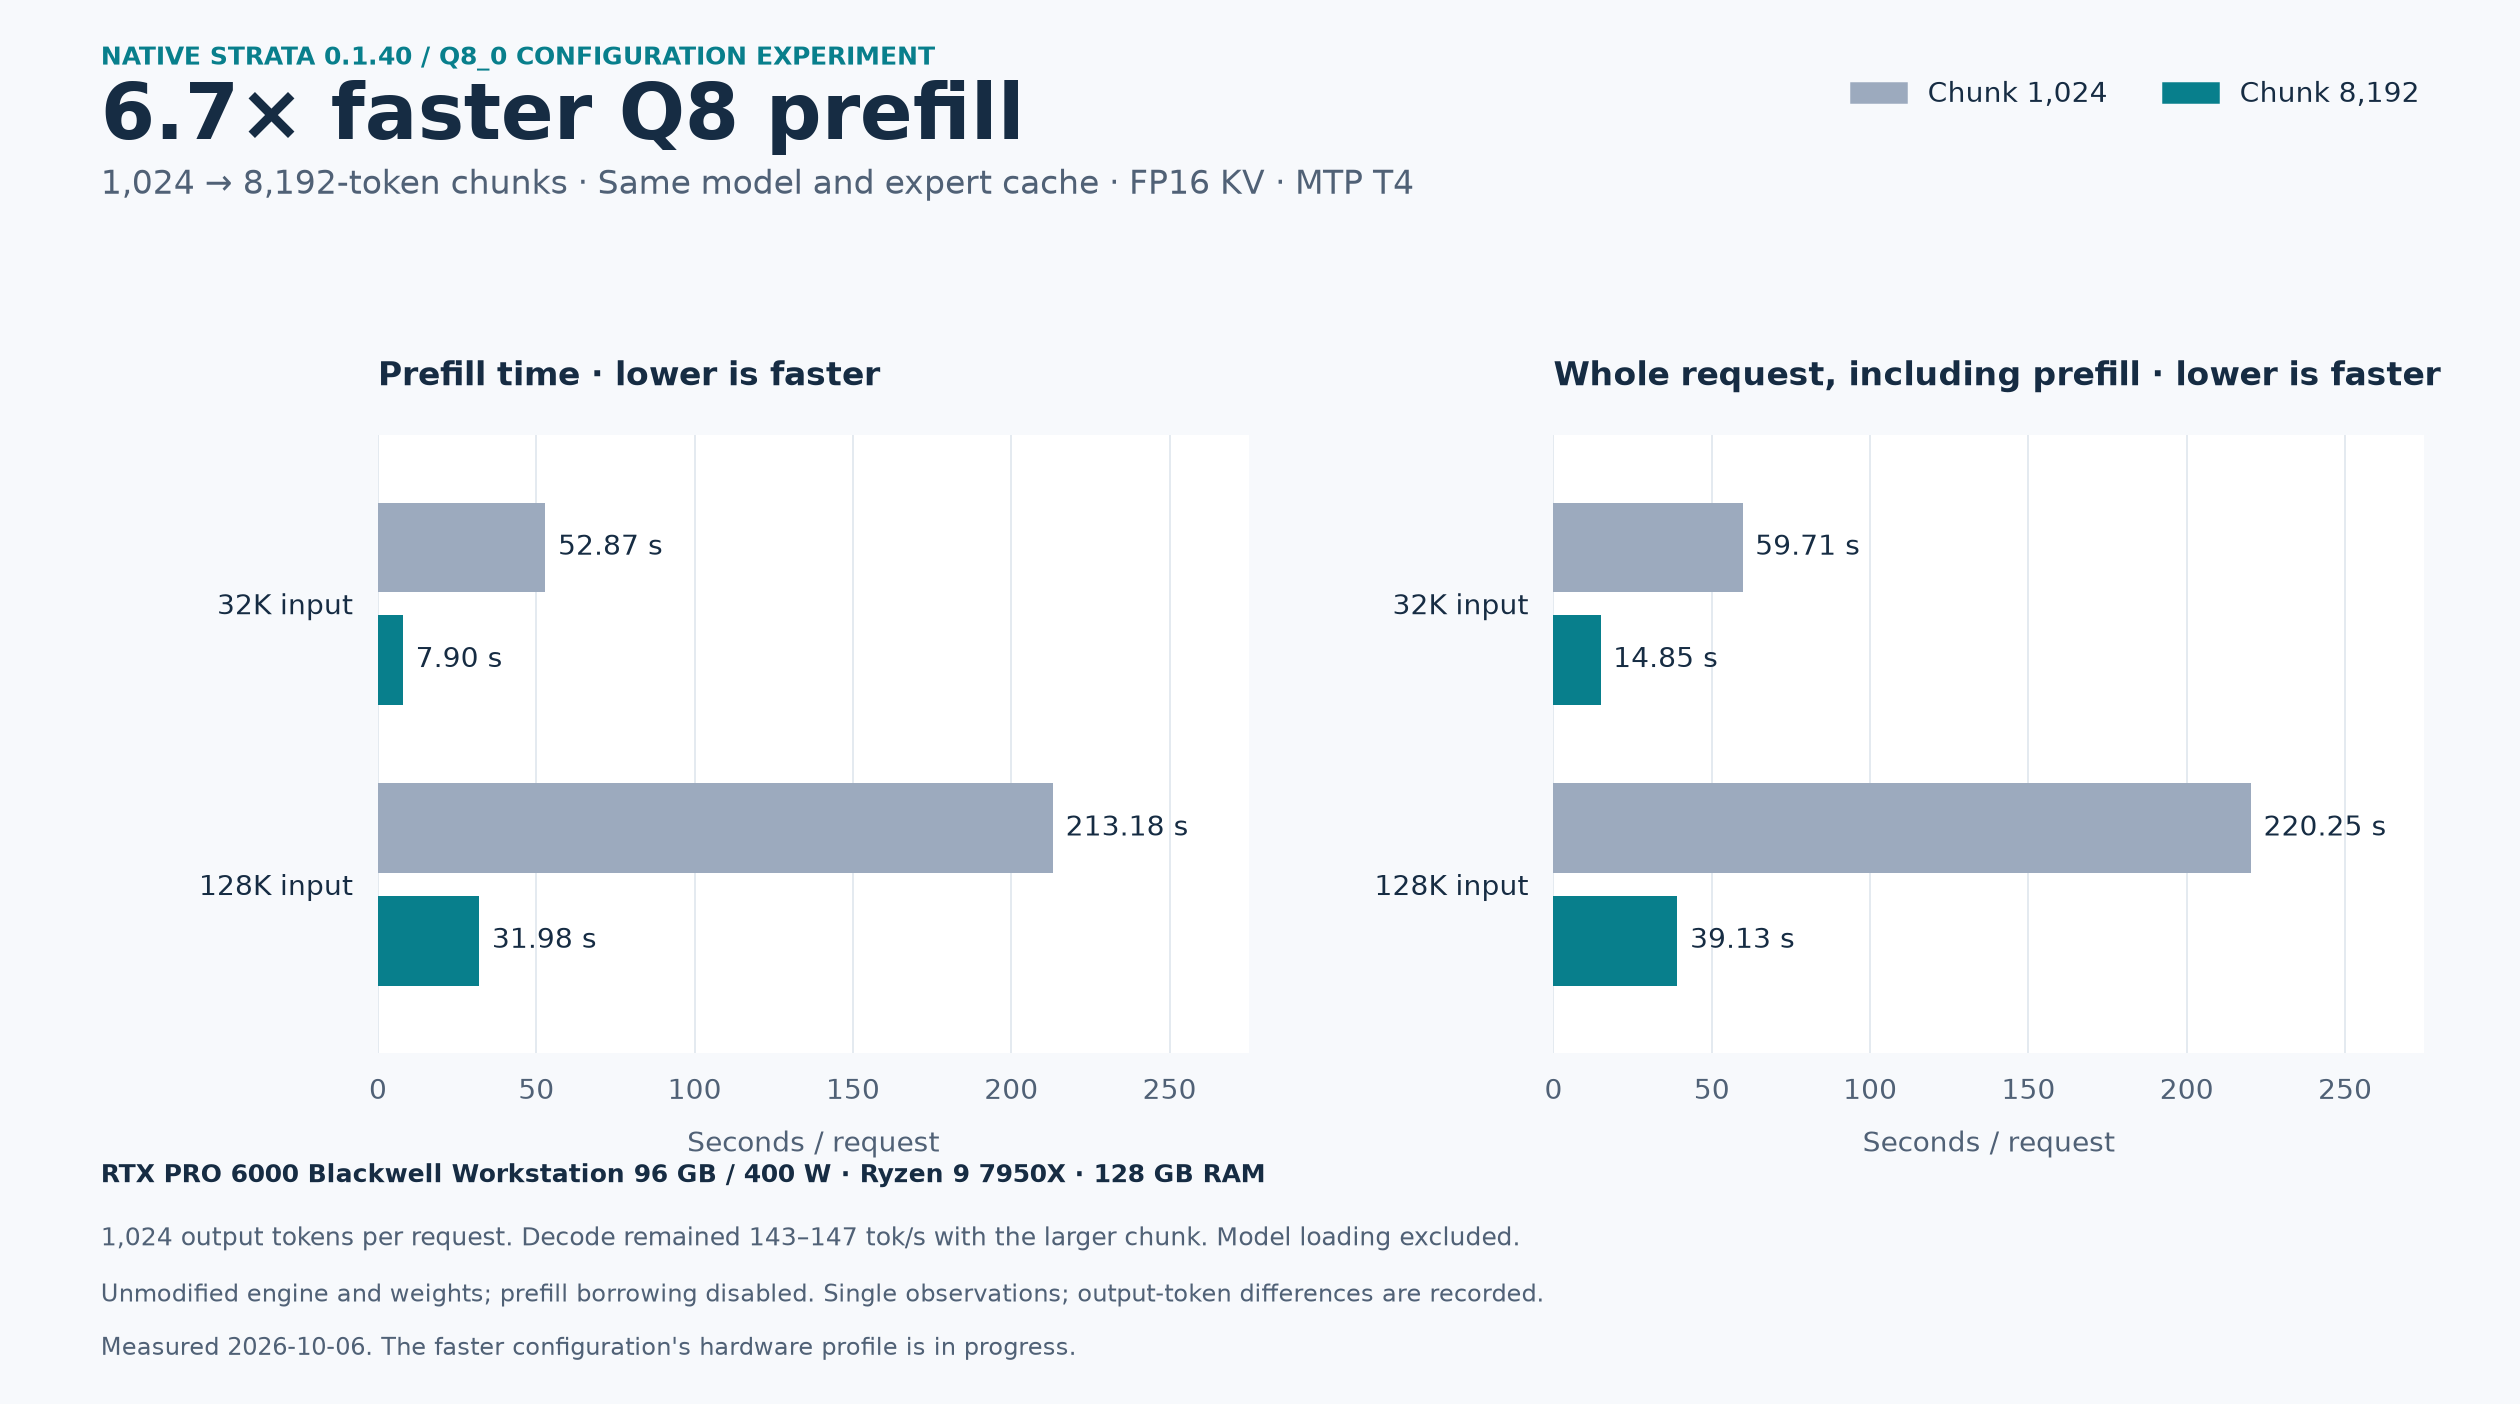 Changing `--prefill 1024` to `--prefill 8192` on unmodified **Strata 0.1.40** reduced Q8 prefill time at **32,768 input tokens**: | Metric | Chunk 1,024 | Chunk 8,192 | |---|---:|---:| | Prefill | 52.87 s | **7.90 s (6.70x faster)** | | Total request | 59.71 s | **14.85 s** | | Output throughput | 149.8 tok/s | 147.3 tok/s | **Hardware:** RTX PRO 6000 Blackwell Workstation Edition 96 GB, 400 W; Ryzen 9 7950X; 128 GB RAM. **Model/settings:** Unsloth Qwen3.8-Flash-Next Q8_0, FP16 KV, MTP T4, ngram off, 1,024 output tokens, 15,472 GPU expert slots, 56 GiB resident expert budget, prefill borrowing disabled. Same weights, expert cache and adaptation settings in both runs. [Configuration and measurements](https://github.com/CC-David-CC/Strata-a5500/blob/a810bf5e5f8cde4de2c6136bff90a637249ab657/bench/results/2026-10-06-q8-prefill8192-rtxpro/README.md)
関連リンク
インストール・モデル・リリースへの站内リンク。