Pull requests / #696
#696 web: saved chats and projects on the server, a file viewer, a coding agent, engine start/stop (#361)
closed · @homeofe · 0 comments · View on GitHub
BenchmarksServer & APIMulti-GPUAMD / HIPNVIDIA / CUDAModels & quantsDocumentationWindowsLinux
Description
Sorry for the delay on this one: the PC that runs it also hosts 35 local CI runners for other projects, which kept it busy (and made clean benchmarks hard, see below). This follows up **#361** (chat history, closed with "a PR is very welcome") and supersedes my first version **#504** (the sidebar kept in `localStorage`). @XeonG asked on #504 what it looks like, so there are screenshots below and in the new [docs/WORKSPACE.md](https://github.com/homeofe/Strata/blob/web-workspace-projects/docs/WORKSPACE.md). It is a lot bigger than the `localStorage` sidebar you described in #361. I have been running it here since 2 October; if you would rather take it in parts, I can split it (1. sidebar with chats on the server, 2. Files and Settings tabs, 3. the coding agent, 4. engine start/stop). 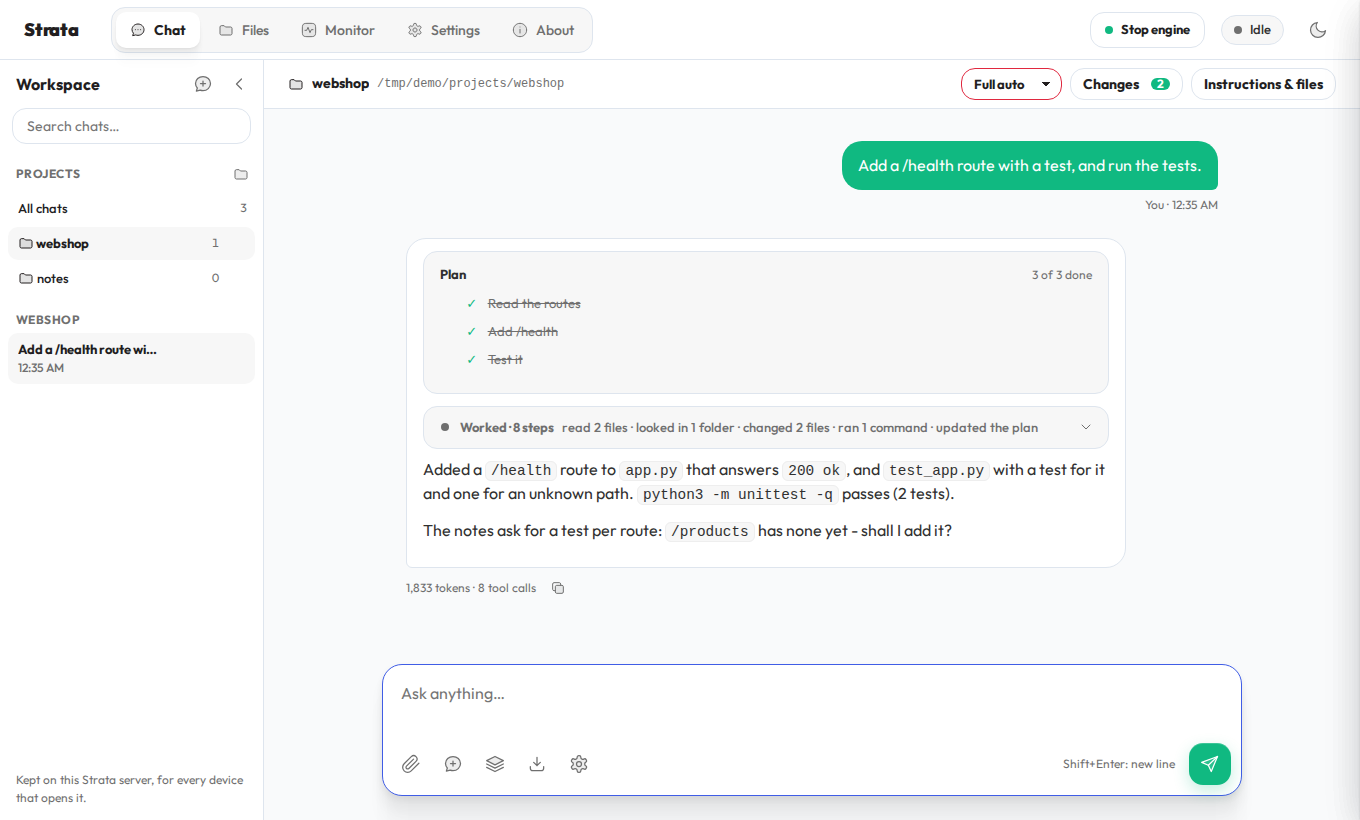 ## Problem The page forgets a chat when it is closed, and #504 keeps chats in one browser only. Beyond history, there was no way to keep work apart (projects with their own instructions and files), to let the model work in a folder, or to free the GPU without stopping the whole server. ## Change - **Chats on the server, in a sidebar**: new, rename, delete, move to a project, search across all chats. Chats a browser kept with #504 move to the server once. `serve/workspace.py`, `POST /workspace/<op>` (API key, JSON and Strata's own page, like `/settings`). - **Projects**: name, instructions sent first in every chat, text files that go with every message, an optional folder; per project the tool rounds per answer (default 200, then Continue; 0 = none) and the compaction threshold (default 100,000 tokens; 0 = never). - **A coding agent** in a project with a folder: `list_dir`, `read_file`, `search`, `find_files`, `write_file`, `edit_file`, `run_command` (live output, timeout, background jobs, Stop), `update_plan` (a plan card). The folder's `AGENTS.md`/`CLAUDE.md` is sent as its guide, and skills in `.agents/skills/*/SKILL.md` are listed for the model to read. The agent loop runs in the page over the existing streamed tool calls. - **Permission modes** per project: Read only (enforced by the server), Ask first (Allow / Allow all in this answer / Always allow / Deny), Auto-edit, Full auto; "Always allow" rules never match a command that chains, pipes or redirects. - **Long runs**: compaction (automatic past the project's threshold, and a Compact button), the round limit with Continue, and from the fourth step the work folds into one line that shows the last steps while it runs; approvals and running commands stay visible. - **Changes in this chat**: a tab per changed file, its diff with old and new line numbers, Undo file / Undo all. - **Files tab** (shared folders, read only): Markdown as a document, code with colours and line numbers (marked, DOMPurify and highlight.js are served from `serve/web`, see `VENDOR.md`; nothing is loaded from the internet). **Settings tab**: API key, theme, and the shared folders; the page refuses the whole disk, the home folder and folders holding `.ssh`, `.gnupg`, `.aws`, `.kube`, `.password-store` or `credentials`. - **Start / Stop engine** (opt-in, `--engine-background`, `serve/engine_control.py`): the web server answers at once and loads the model on a thread; the header button shows the start's progress from the engine's log and, while the experts are read, the engine's memory against the last start. Stop unloads and keeps it unloaded (requests get a 503 that says so), also across restarts. Without the flag nothing changes. `Vision` can now start with the engine instead of at server start (`lazy`). - `serve/server.py` only gets the hooks: the `/workspace/` and `/engine` routes, `--workspace-dir`, `--workspace-root`, `--engine-background`, a hold check in `ensure_loaded`. No version bump. Based on `main` at `99f3dbd` (0.1.38). <details><summary>More screenshots</summary> 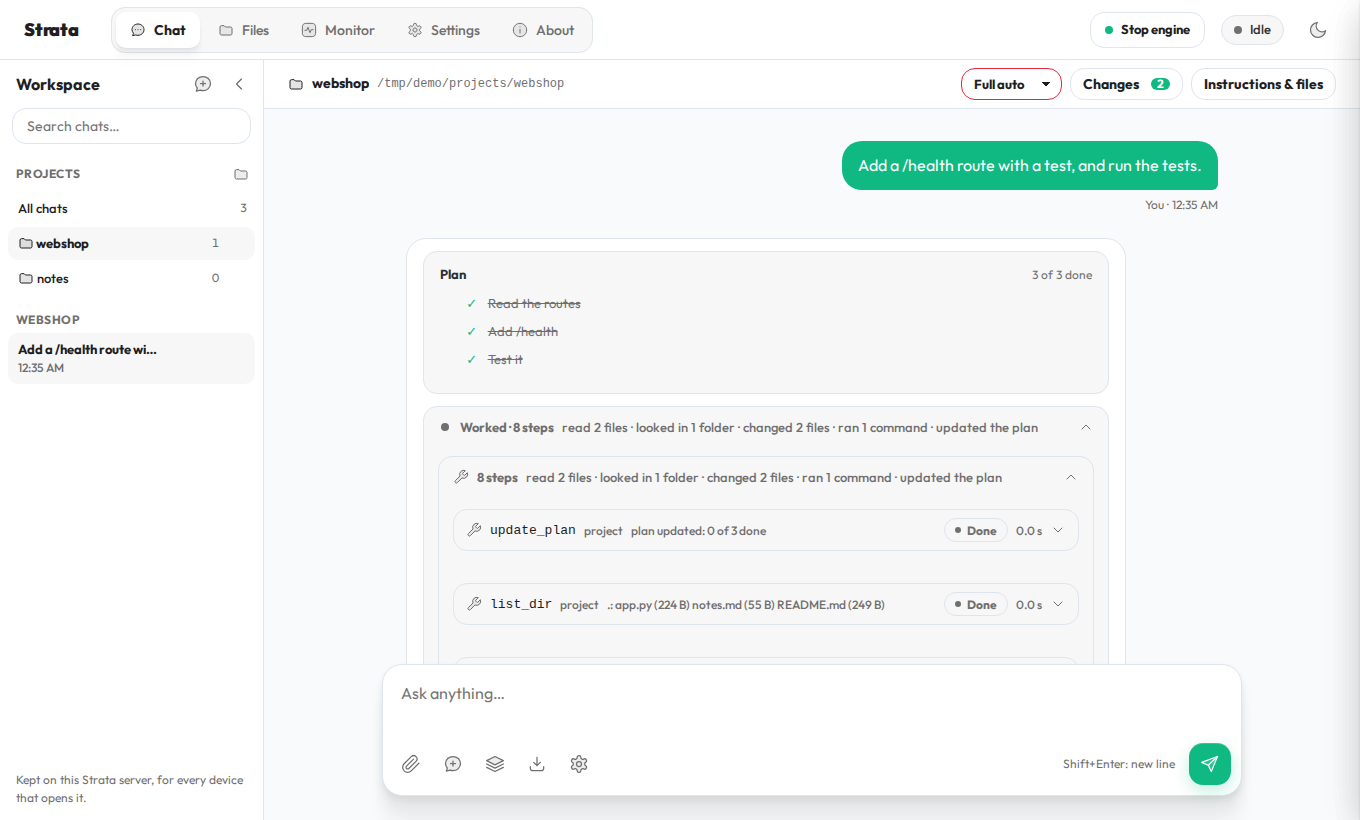 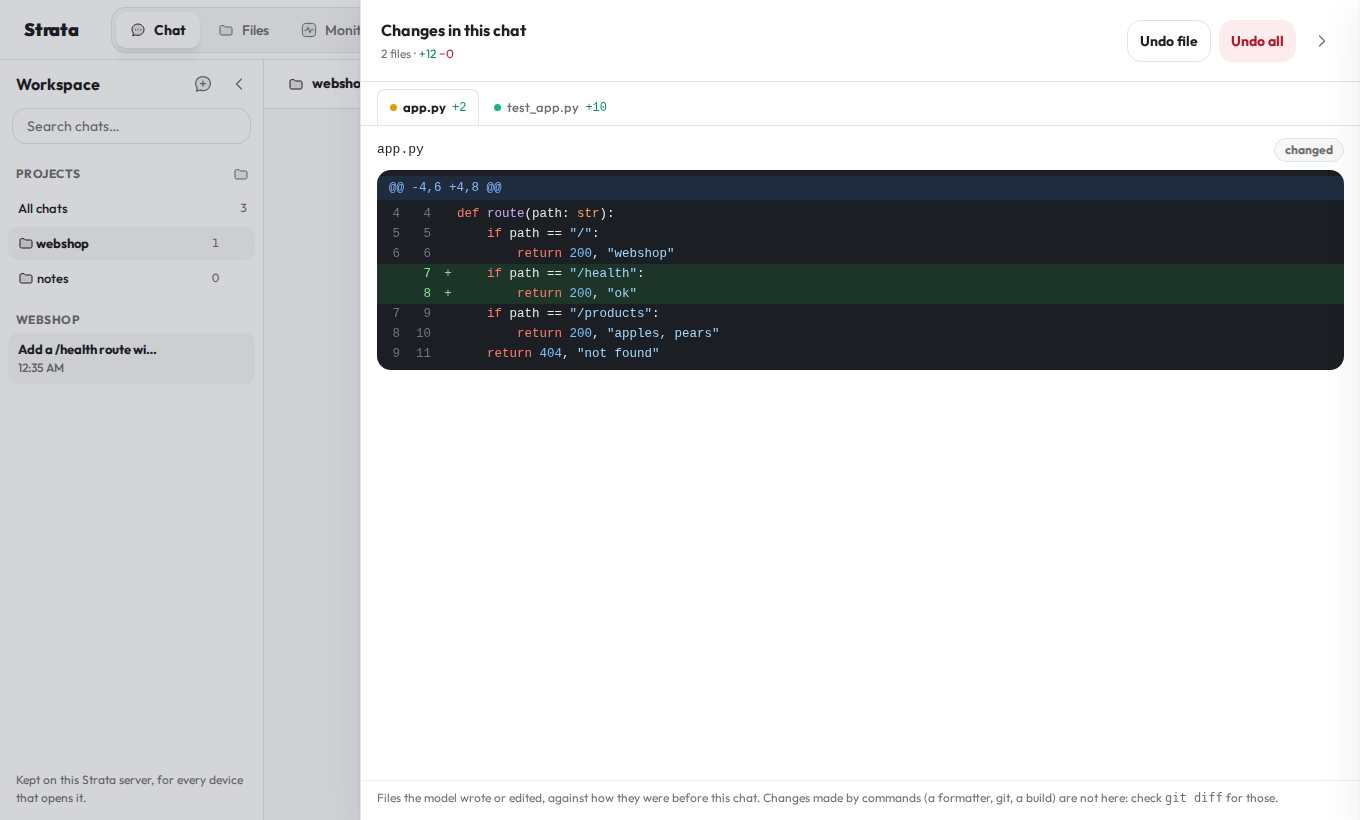 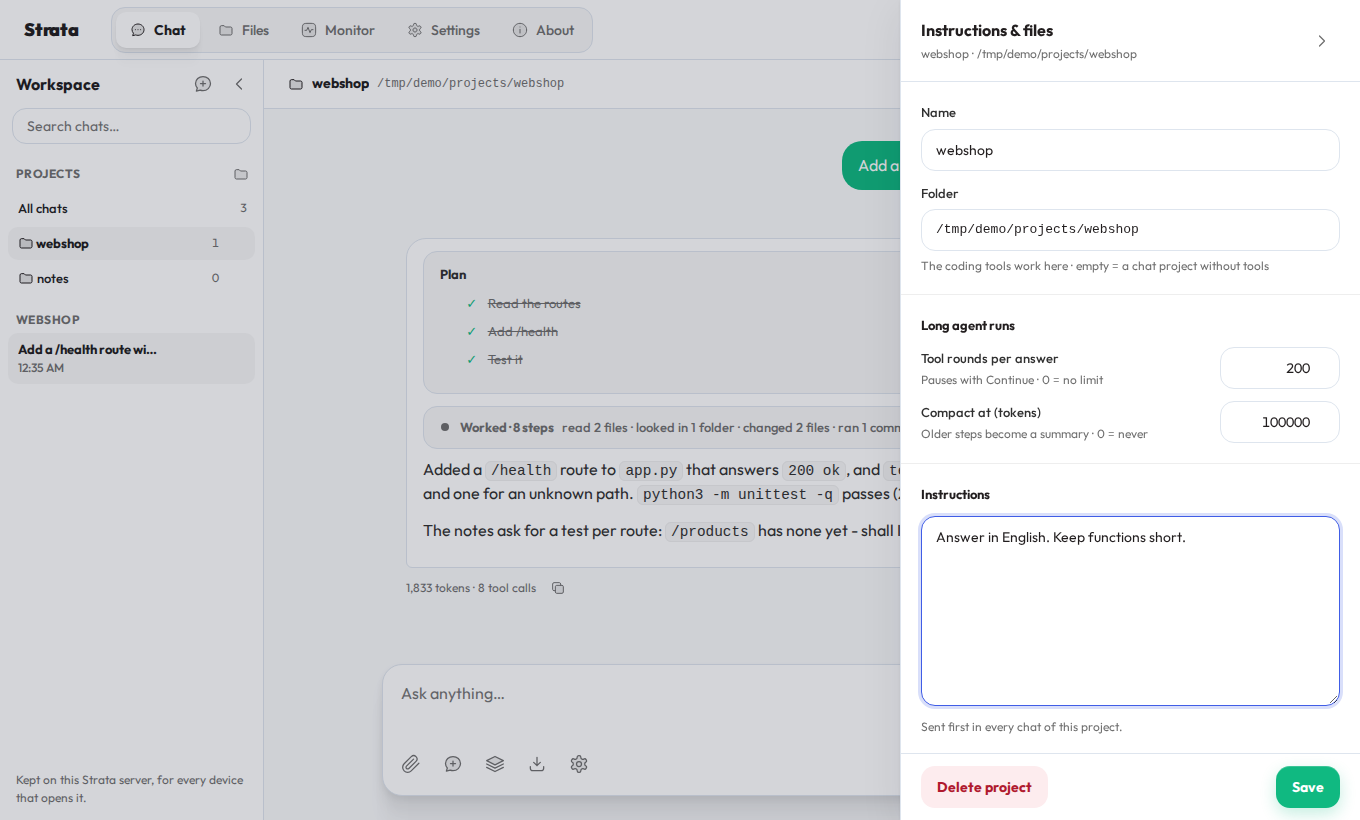 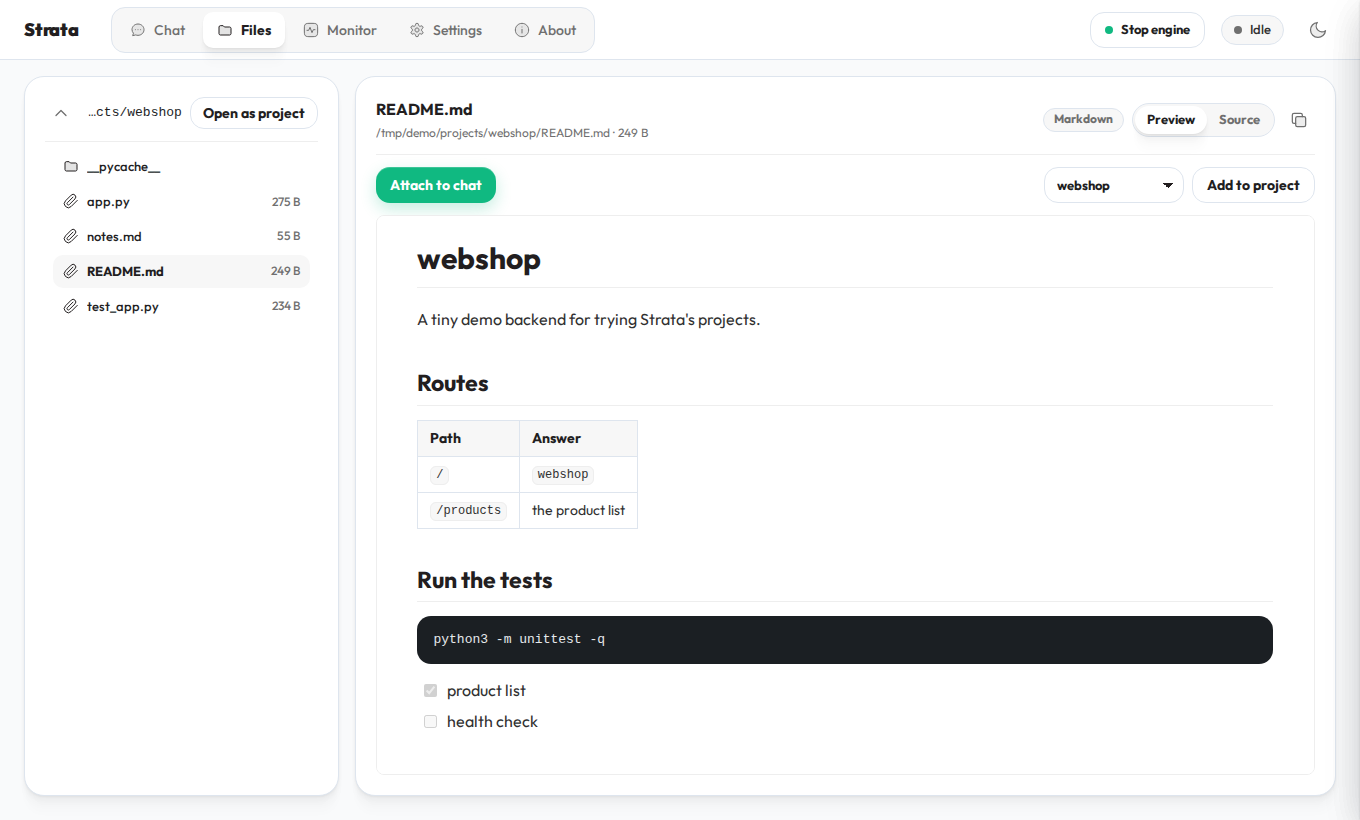 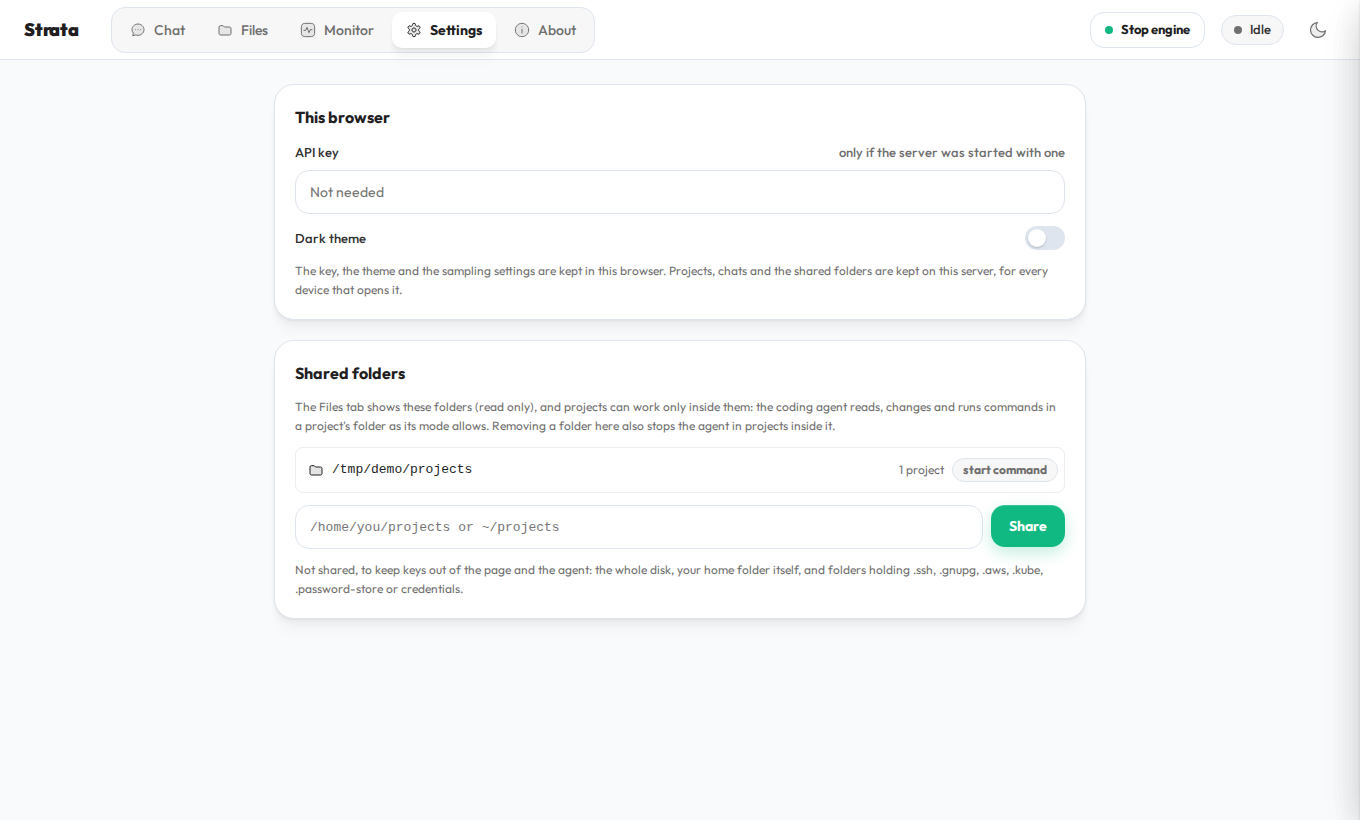 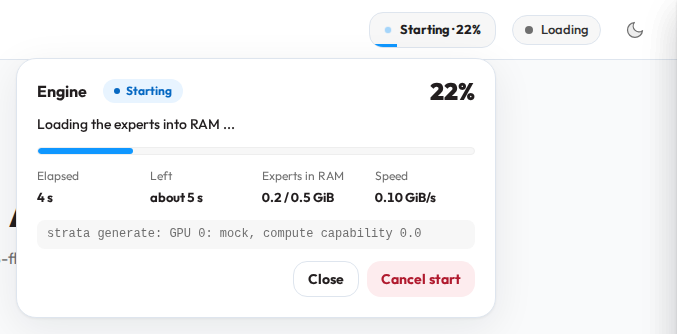 </details> ## Tests - `python -m unittest discover -s serve -t . -p "test_*.py"`: 226 tests OK (9 skipped), with the new `serve/test_workspace.py` (storage, explorer and shared folders, the coding tools and their confinement, jobs, changes and undo, allow rules, skills, HTTP guards) and `serve/test_engine_control.py` (background start and progress, Stop with the 503, a cancelled start, a stop kept across restarts, HTTP guards; with a mock engine that starts like the real one). - Browser checks with Playwright against the mock engine: agent loop, approvals, live command output and Stop, changes and undo, plan, folding, compaction, round limit, allow rules (84 checks); sidebar, projects, search, Files, attach (33); engine button (17); Files viewer and Settings (31), at 1280 px and 390 px, light and dark, no console errors. - On the real model here since 2 October (numbers below). ## Measured on this PC RTX 2080 Ti 11 GB (PCIe 3.0 x16, the engine's probe: 13.1 GB/s), Threadripper 3960X (24 cores, AVX2, no AVX-512), 128 GB RAM, Ubuntu 24.04, driver 580.178.04, CUDA 12.0, engine compiled for sm_75. Flash-Next **IQ3_S**, 262,144 context, int8 KV with 32,768 positions resident, MTP, image encoder on the CPU. **Engine start and stop from the page** (`--engine-background`, 0.1.38): | | measured | | --- | --- | | web page answering after a service restart | about 1 s (the model still loading) | | engine start, warm file cache | 54-86 s | | engine start, cold or with the CI busy | 140-200 s | | of which reading the experts (46.84 GiB) | about 25-30 s at 1.8-2.5 GiB/s, measured from the engine's memory | | of which locking them for the GPU | 20-130 s (no counter: timed against the last start) | | Stop | 7.8 s; afterwards 11 MiB of GPU memory and 11 GB of RAM in use | **This machine's own engine jump, 0.1.35 → 0.1.38** (the server and web app here are on `main` + this PR). The CI runners kept the load at 20-55 on 24 cores, so single runs swung by about ±30%; the versions ran interleaved (round 1: A B C, round 2: A B C) so each saw the same load. 4K code prompt, greedy, 256 tokens, thinking off, a fresh prompt per run, numbers from `/metrics`: | engine | prompt tok/s (median) | decode tok/s (median) | draft acceptance | | --- | ---: | ---: | ---: | | 0.1.35 | 468 / 615 (two runs) | 28.2 / 36.0 | 0.68 | | 0.1.38 (round with the first 0.1.35 numbers) | 649 | 29.9 | | | 0.1.38 + #655 | 632 | 31.6 | 0.69 | | 0.1.38 + #655, `--pcie-frac 0.28` | 658 | 30.6 | 0.67 | | 0.1.38 + #655, `STRATA_ADAPT_NOWAIT=1` | 667 | 29.7 | 0.72 | So: no consistent difference between 0.1.35 and 0.1.38 on this card (the first run had 0.1.38 behind on decode, the second ahead), neither #485's probe (it now picks `pcie_frac` 0.36 at the same 13.1 GB/s, 0.1.35 picked 0.28) nor #463's wait made a consistent difference, and the prompt numbers point the way #655 says. A clean before/after needs a quiet machine; I did not get one. ## Other PRs I run alongside (not in this diff) Listed so you can judge them yourself; each was applied as its own commit on top of 0.1.38 here: - **#655** (BF16 products on the FP16 tensor cores, sm_75): `gemm_bf16_parity` passes on this 2080 Ti, worst relative difference 1.7e-5; per product, cuBLAS BF16 → the PR: hc down 4,858 → 1,691 µs (2.87x), hc up 3,483 → 571 µs (6.10x), PLE value 1,337 → 298 µs (4.48x), router/indexer q 319 → 62 µs (5.18x), hc inject 1,187 → 48 µs (24.6x), single row 21.6 → 21.6 µs (unchanged, by design). - **#547** and **#583**: they overlap; #583 applies on top of #547 if its two loan calls keep #547's new `src` argument (`bytes_needed(g, ss, c, srcp != nullptr)`). With both, the IQ3_S prompt ring here is 199 slots instead of 384. - **#603** (1,024-thread top-k): `qsa_topk_parity` and `qsa_topk_active_parity` pass on sm_75. - **#646**: conflicts with #603 in `qsa_select.cu` (both change the dispatch past the register kernel's reach); I kept #603's dispatch there and the rest of #646. Its biggest part needs every routed expert in VRAM, which 11 GB never has, so I expect little from it on this card; the IQ/MMVQ parity tests pass. - **#622** (opt-in AVX2 gather) and **#614** (opt-in): built in, switched off. - **#650** (THP for the expert arena): **tried and taken out again.** With `transparent_hugepage/defrag = madvise` (Ubuntu's default) and 60+ GB of file cache, `MADV_HUGEPAGE` sent the arena's page faults into direct compaction: the engine sat at the arena for more than 400 s, twice (`compact_stall` 252,190, `compact_fail` 230,221 in `/proc/vmstat`). With all of that: `ctest` 65 of 67 on this card (`ple_parity` needs the Q2_0 fixture, `expert_multi_test` needs AVX-512); the engine starts in 77 s and decodes a 137-token answer at 32.9 tok/s with the CI still running. ## Not run Windows and AMD (the page and server changes are platform-independent Python and JavaScript, but I only ran them on Linux); multi-GPU.
Related on strata.com
Editorial links to help you install, pick models, or read release notes — not part of the upstream thread.