Pull requests / #3060
#3060 STRATA_RAM_ADAPT: copy an incoming expert out of its stage buffer instead of a second file read
open · @SanghunYun · 0 Kommentare · Auf GitHub
BenchmarksServer & APIAMD / HIPNVIDIA / CUDAModels & quantsDocumentation
Beschreibung
## Title STRATA_RAM_ADAPT: copy an incoming expert out of its stage buffer instead of a second file read Issue: follow-up to #1837 / #1838 (in main as d7298883) ## Summary On #1838 you measured no gain on the bench and a decode loss. We reproduced it on the `strata_bench.py` normal suite (short chat −3.4% with `STRATA_RAM_ADAPT=8`). The option only pays off once the RAM copy has followed a conversation for a while, and every move cost a file re-read on the decode thread (~0.77 ms, 8 moves per window), so a short request ended before the moves paid back. This change makes a move a memcpy out of the stage buffer the demand read just filled (~0.1 ms). Result: the short bench no longer loses (+3.2% decode, prefill unchanged), and the long sessions this option is for gain clearly: **+33.8% decode on 120 ShareGPT requests** and +19.2% on a 47-request session, with cumulative time down 23% / 13%. ## What changed - `src/core/expert_source.cpp`, `include/strata/core/expert_source.hpp`: `replace_resident_staged()` moves a pair when the incoming blob is still in a finished stage buffer; the buffer is held under `stage_mu_` during the copy; same Foresight hold and between-window checks as `replace_resident()`. Counter `ram_staged()`. - `src/program/generate.cpp`: the `STRATA_RAM_ADAPT` loop tries the staged copy first for every ranked pair (up to one per layer per window); `STRATA_RAM_ADAPT=<n>` now caps only the pairs that still need a file read (1 is enough). Pair selection, thresholds and the stage buffers' size and reuse are unchanged; still opt-in. The stats line counts staged moves. - `tests/core/file_expert_source_test.cpp`: a staged move writes the exact bytes, refuses an unstaged or invalid pair and leaves the other experts untouched (pinned and pageable). - `docs/DETAILS.md`: the `STRATA_RAM_ADAPT` entry. ## Extra Notes v0.1.45 + this commit, RTX 3060 12 GB, IQ2_XS, 3769 VRAM expert slots, `--resident-budget-gib 20.5` (~74% of the experts outside the GPU), NVMe. Fresh process per run, `STRATA_RAM_ADAPT=1`. Engine arguments and environment, identical in every run except `STRATA_RAM_ADAPT` (unset for OFF, `1` for ON): ``` strata --serve --prefill auto:16384 --spec 3 --mtp-max-t 3 --spec-min-p 0.5 --suffix-draft 0 --max-context 131072 --kv k8v4 --pool-workers 7 --ple-io direct --greedy --stop-eos --stats --mmap-experts --mtp <mtp dir> --prompt-cache-root 1024 --prompt-cache-every 0 --conversation-cache-min-free-mib 1280 --tail-role-token 8678 --conversation-cache-min-tokens 3072 --pack <IQ2_XS pack> --native <IQ2_XS gguf> --expert-profile <stock profile> --resident-budget-gib 20.5 --expert-cache 4200 --vram-reserve-mib 768 --adapt-async 1 --conversation-cache-mib 1536 --conversation-cache-slots 3 --prompt-cache 2 STRATA_UNBUFFERED_LOAD=1 STRATA_STAGER_THREADS=8 STRATA_STAGER_RING=32 STRATA_LOOKAHEAD=1 STRATA_PREFILL_CPU_SHARE=auto STRATA_RESIDENT_HEADROOM_GIB=0 STRATA_ADAPT_OVERLAP=0 STRATA_ROUTE_TAIL_SKIP=7 CUDA_MODULE_LOADING=LAZY ``` `--expert-cache 4200` got 3769 slots; temperature 0; `serve/server.py` behind our local logging wrapper (the kit replays against plain `serve/server.py`). | Workload | Decode tok/s<br>OFF → ON | Prefill tok/s<br>OFF → ON | SSD expert reads / token<br>OFF → ON | | --- | --- | --- | --- | | `strata_bench.py` normal suite (15 req., short) | 38.7 → 39.9 (+3.2%, no loss) | 446 → 445 (−0.2%) | 15.9 → 9.7 (−39%) | | ShareGPT, 30 conversations × 4 turns (120 req.) | 36.6 → 48.9 (**+33.8%**) | 119 → 142 (+19%) | 22.9 → 4.5 (−80%) | | English 47-request session (in the kit) | 43.7 → 52.1 (**+19.2%**) | 277 → 292 (+5%) | 12.6 → 0.9 (−93%) | Runs were OFF, ON, OFF; OFF in the table is the run after ON. The OFF run before ON gave 38.3 / 36.5 / 44.1 decode tok/s, within 1% of the one after. 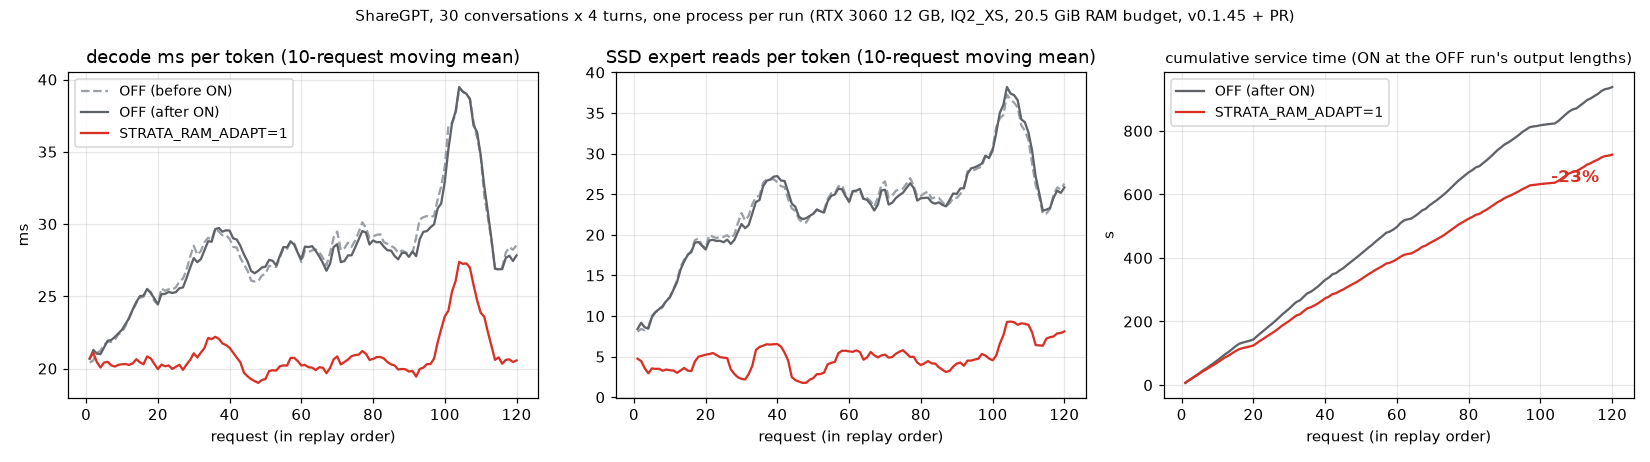 In the long session ON is faster from the first requests and stays there; the cumulative saving grows to 9% after 10 requests, 16% after 30 and 23% after 120. Paired per-request decode-time ratio (ON / OFF): ShareGPT 0.747 (95% CI 0.734–0.761), English 0.839 (0.819–0.861). One run per arm. With a RAM budget below the experts outside the GPU the #669 lend-region warning is printed in every run; that is the case this option is for. Replay: requests, the ShareGPT builder, replay/summary scripts and our per-request numbers are at https://github.com/SanghunYun/Strata/tree/ram-adapt-replay Tests: CUDA sm86 Release `file_expert_source_test --rotation-gpu` passes with the new case. HIP gfx1100 Release (ROCm 7.10): engine and test build and link, host-side `file_expert_source_test` passes; no AMD GPU inference.
Mehr auf der Site
Links zu Install, Modellen, Releases.