Pull requests / #1698
#1698 feat: experimental RoPE to YaRN 4x saved-cache migration
open · @CC-David-CC · 0 Kommentare · Auf GitHub
BenchmarksSetup & installMulti-GPUAMD / HIPNVIDIA / CUDAModels & quantsDocumentation
Beschreibung
## Summary
Convert an ordinary-RoPE saved session into approximate YaRN 4x history, then restore it through the existing slot endpoint. Stages changed keys before committing; retains values, recurrent state, original file and migration provenance. Fresh YaRN is already supported; this adds saved-cache conversion.
## Use
Requires `STRATA_ROPE_TABLE=1` and `--experimental-rope-yarn4-cache` on BOTH engines: single GPU, FP16 KV, MTP off, `--conversation-cache-mib 0`. Start the target with `--rope-scaling yarn --rope-scale 4`.
`POST /slots/0?action=migrate_yarn4`
```json
{"filename":"ordinary.sess","source_context":262400}
```
`source_context` is source allocation capacity. Continue with full conversation history and `max_tokens: 128`. [Complete setup and cache restrictions](https://github.com/CC-David-CC/Strata-a5500/blob/d11e0fee16212023a0ff2a267e1bfb87d9fb6933/docs/ROPE_CACHE_MIGRATION.md).
## Validation
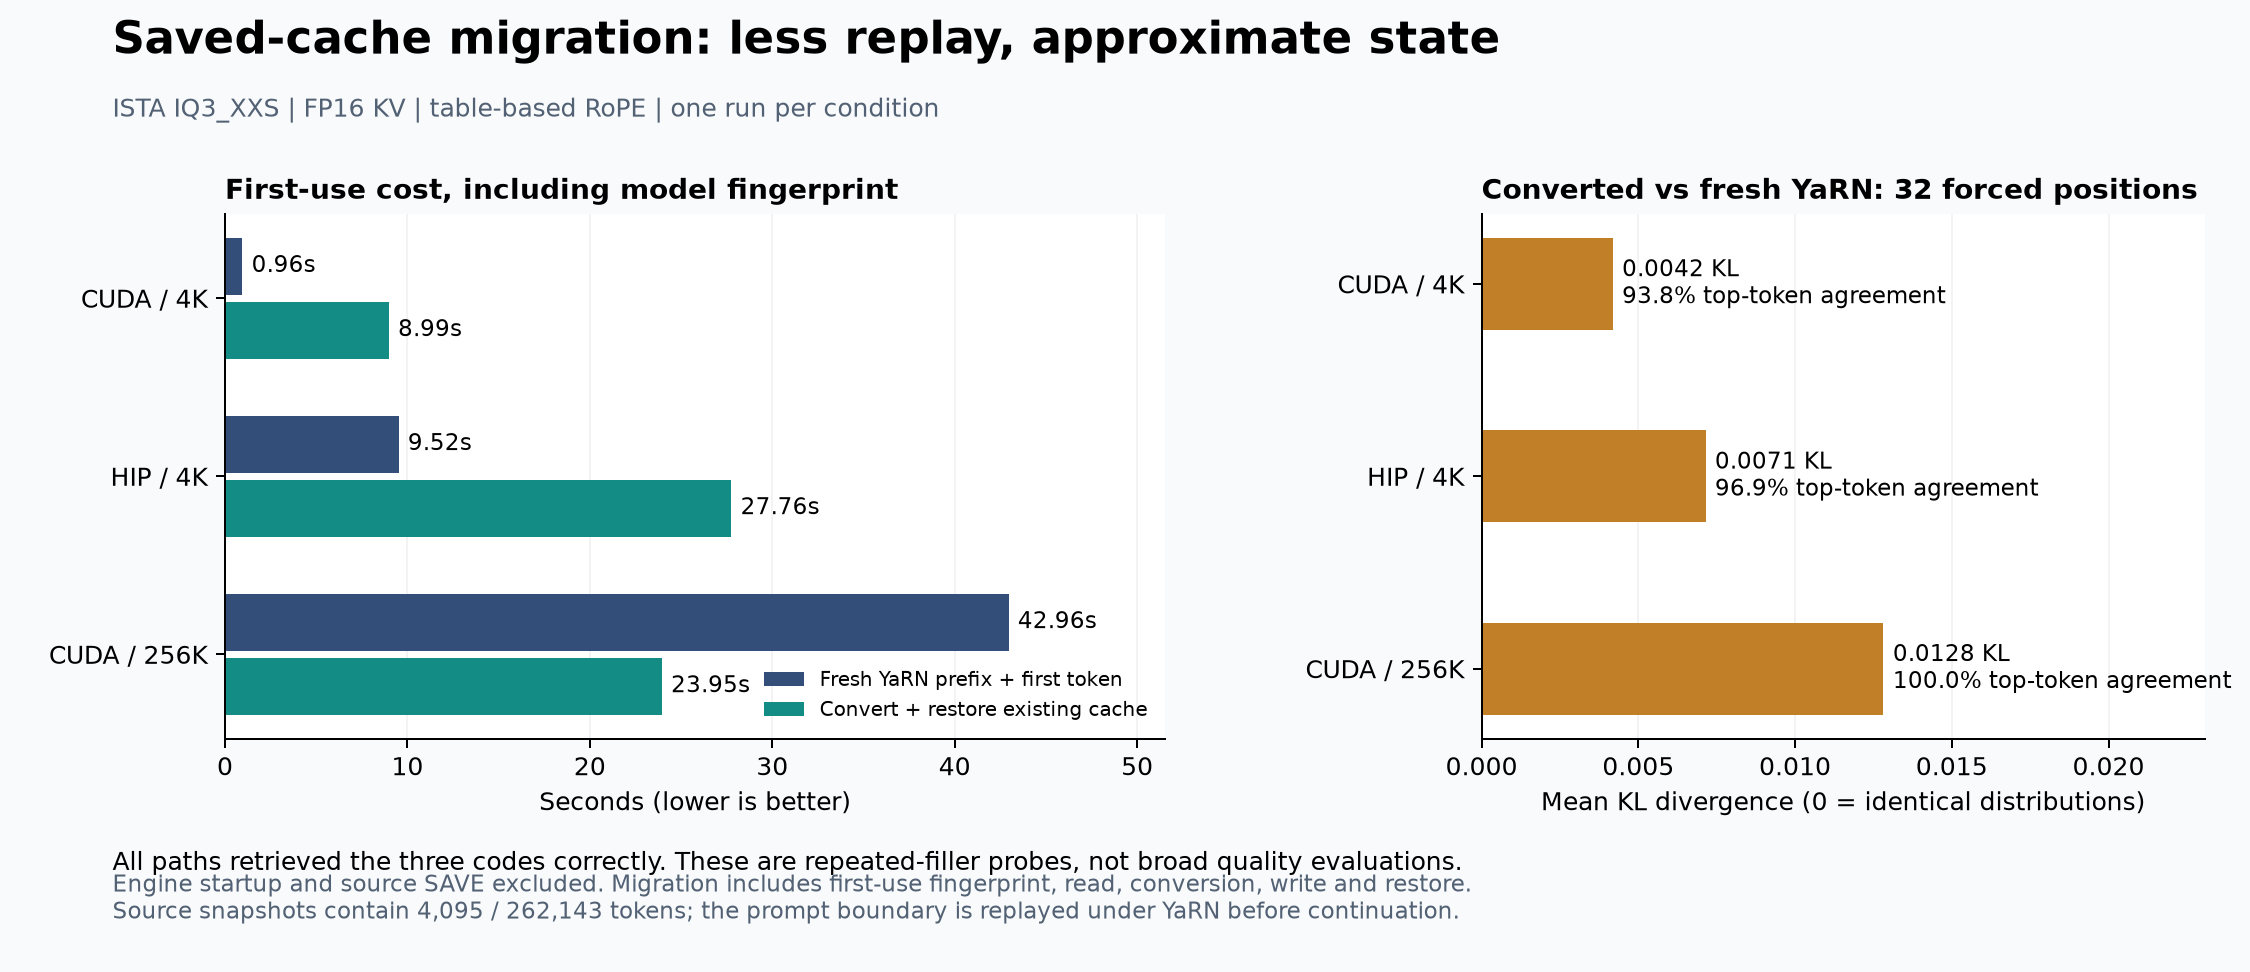
CUDA and HIP: 6 native tests and 34 API tests passed; real 4K save/convert/continue/save/restore passed. CUDA 256K: fresh prefix 42.96 s versus conversion+restore 23.95 s (1.79x); includes first-use model fingerprint. At 4K migration was slower. Over 32 forced positions: mean KL 0.01282, 100% top-token agreement. All three retrieval codes correct; one case is not broad quality proof.
[Raw measurements, controls and reproducible commands](https://github.com/CC-David-CC/Strata-a5500/blob/d11e0fee16212023a0ff2a267e1bfb87d9fb6933/bench/results/2026-10-09-rope-cache-migration/README.md). Unflagged CUDA output matched main's 22 tokens exactly in the 4K control.
## Draft limitations
SYCL build validation pending; keep draft until completed. Full 1M migrated continuation unverified. Quantized/BF16 KV, MTP, multi-GPU, multimodal and analytic fast-math caches are rejected. Defaults unchanged; no automatic switch or merge requested.
Mehr auf der Site
Links zu Install, Modellen, Releases.