Pull requests / #1497
#1497 docs: tool selection and recovery analysis with model-family guide
open · @CC-David-CC · 0 Kommentare · Auf GitHub
BenchmarksNVIDIA / CUDAModels & quantsDocumentation
Beschreibung
## Summary A separate analysis of the completed measurements in #1491, using explicit priorities for agentic coding workflows. Q8 is labeled Reference. This adds no inference runs or engine changes and does not replace the official benchmark scores. ## Weighting Tool selection 25%, error recovery 25%, context/state 20%, arguments 10%, planning 10%, multi-step chains 5%, code patterns 5%. Safety, structured output and all other categories have zero weight. Score = sum(weight * earned category points / available category points), using exact fractions before rounding. These are preference weights, not a validated coding-success probability. 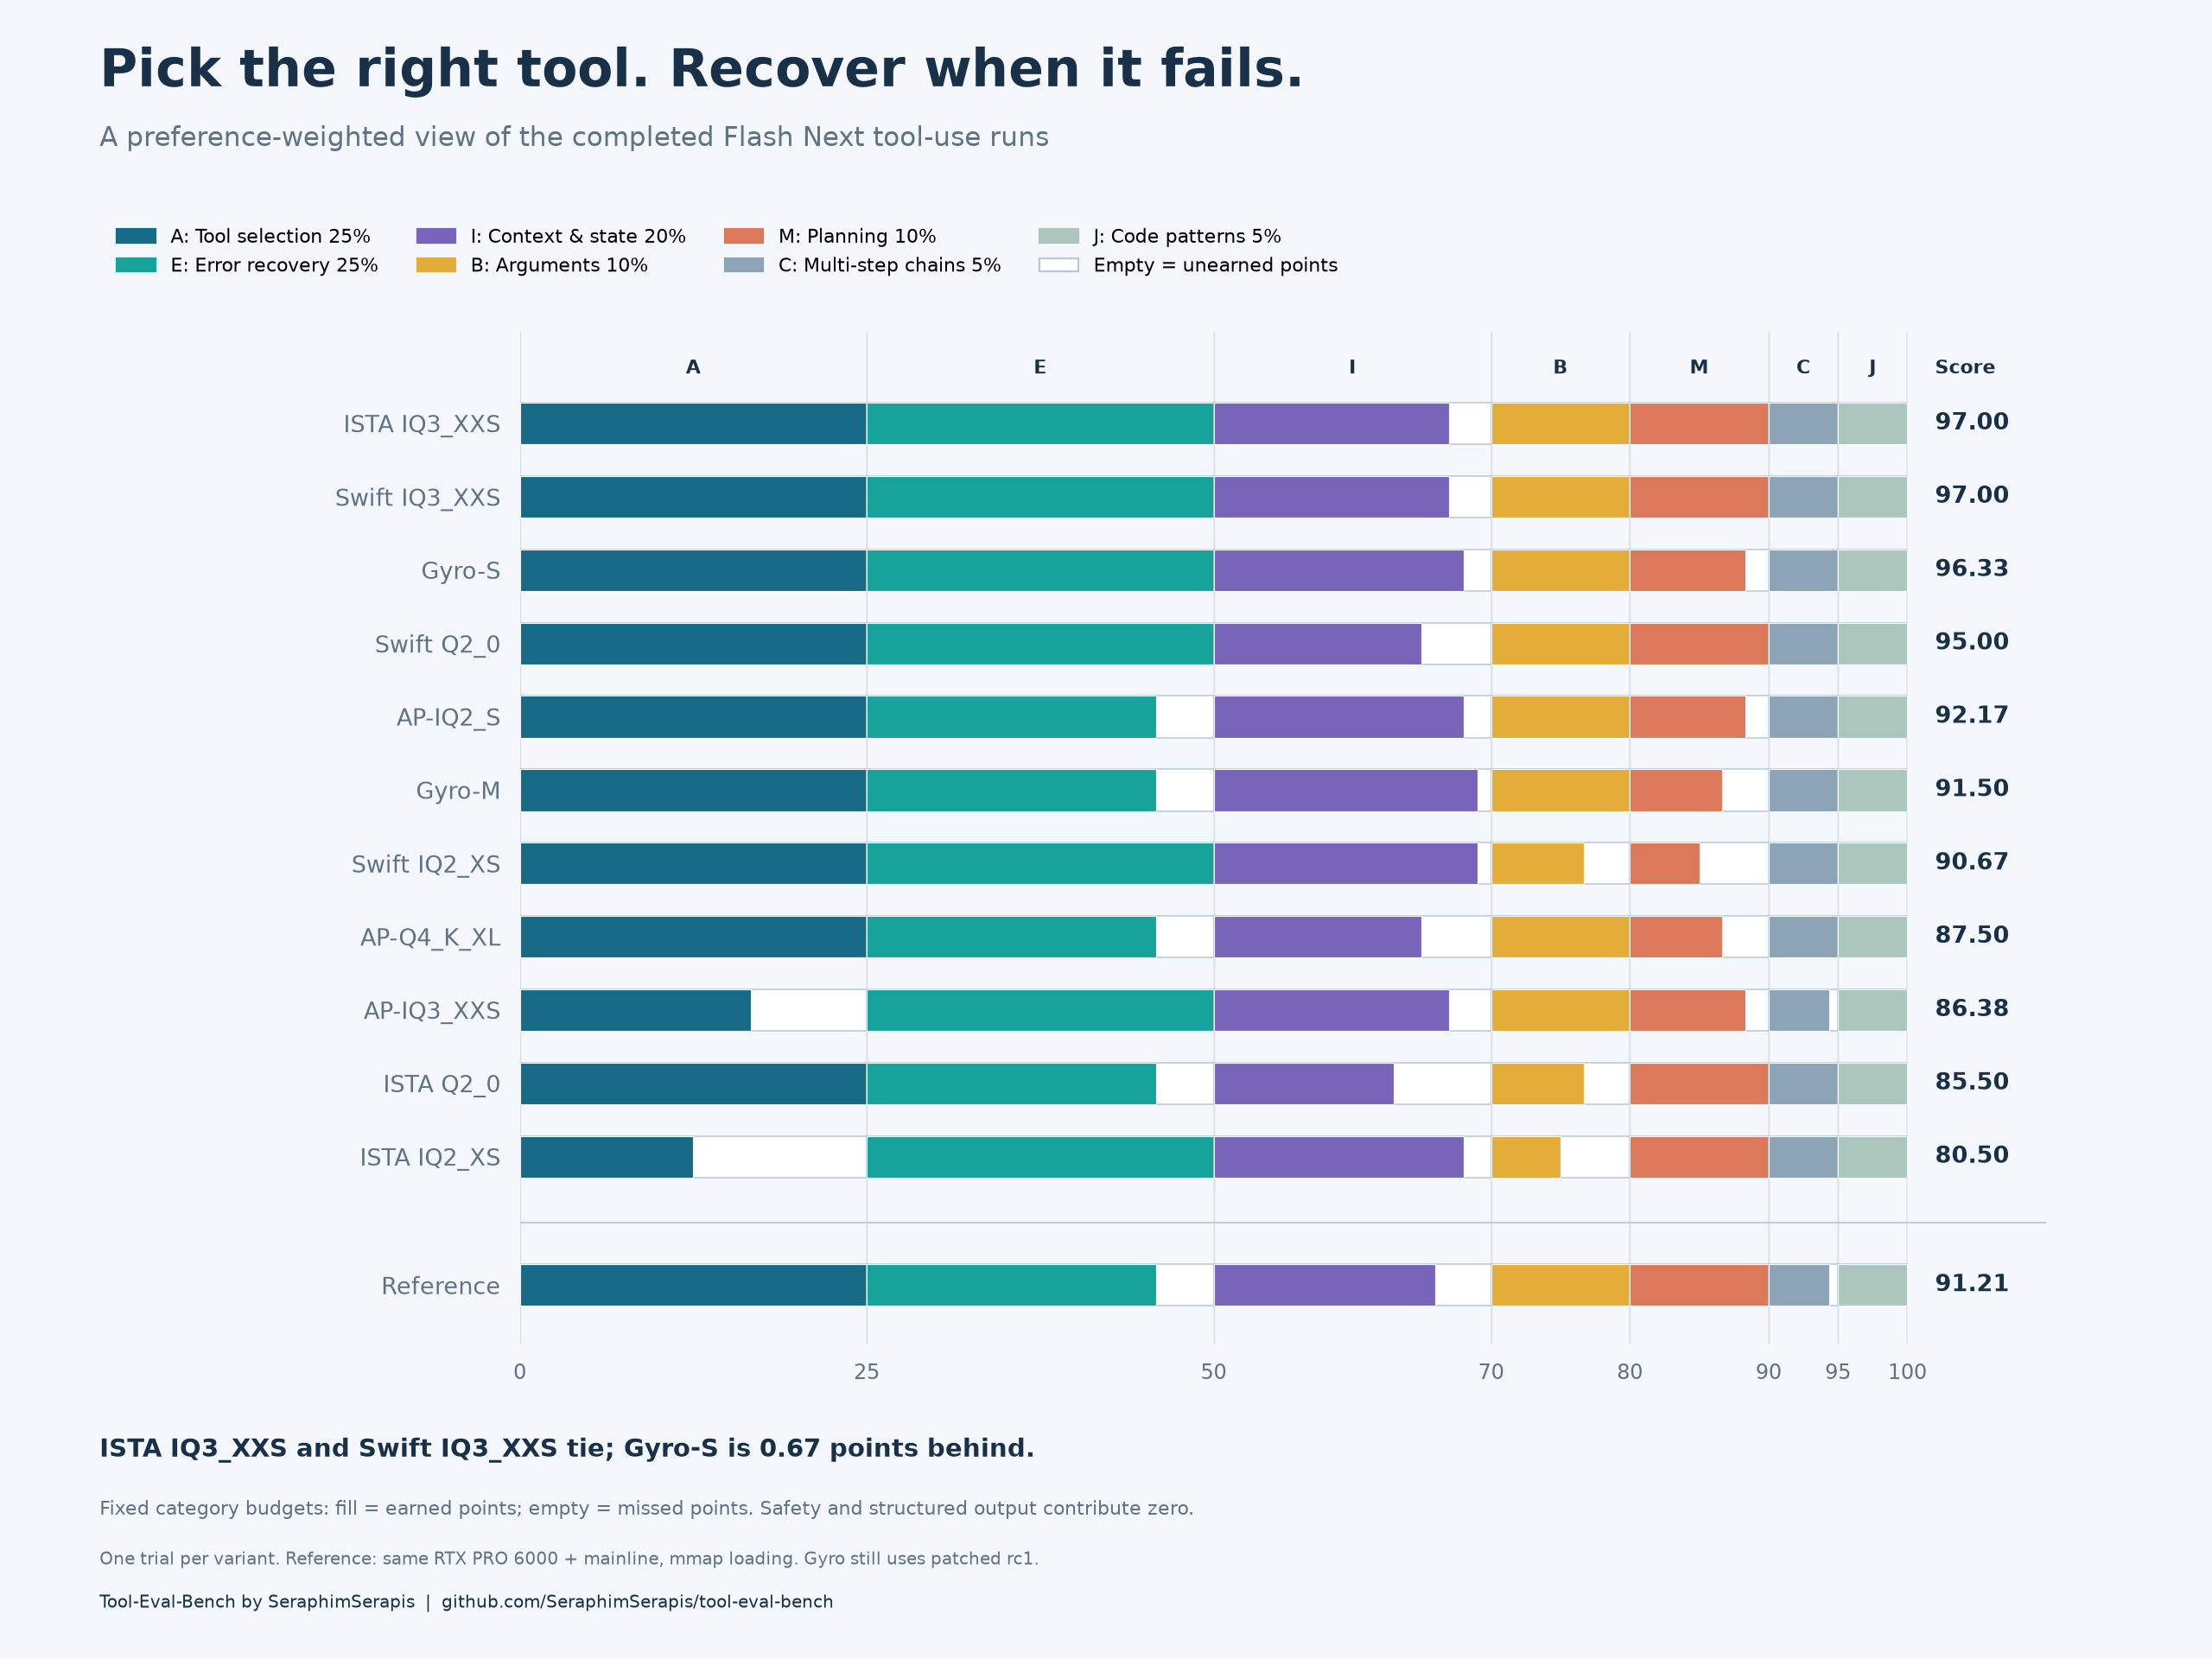 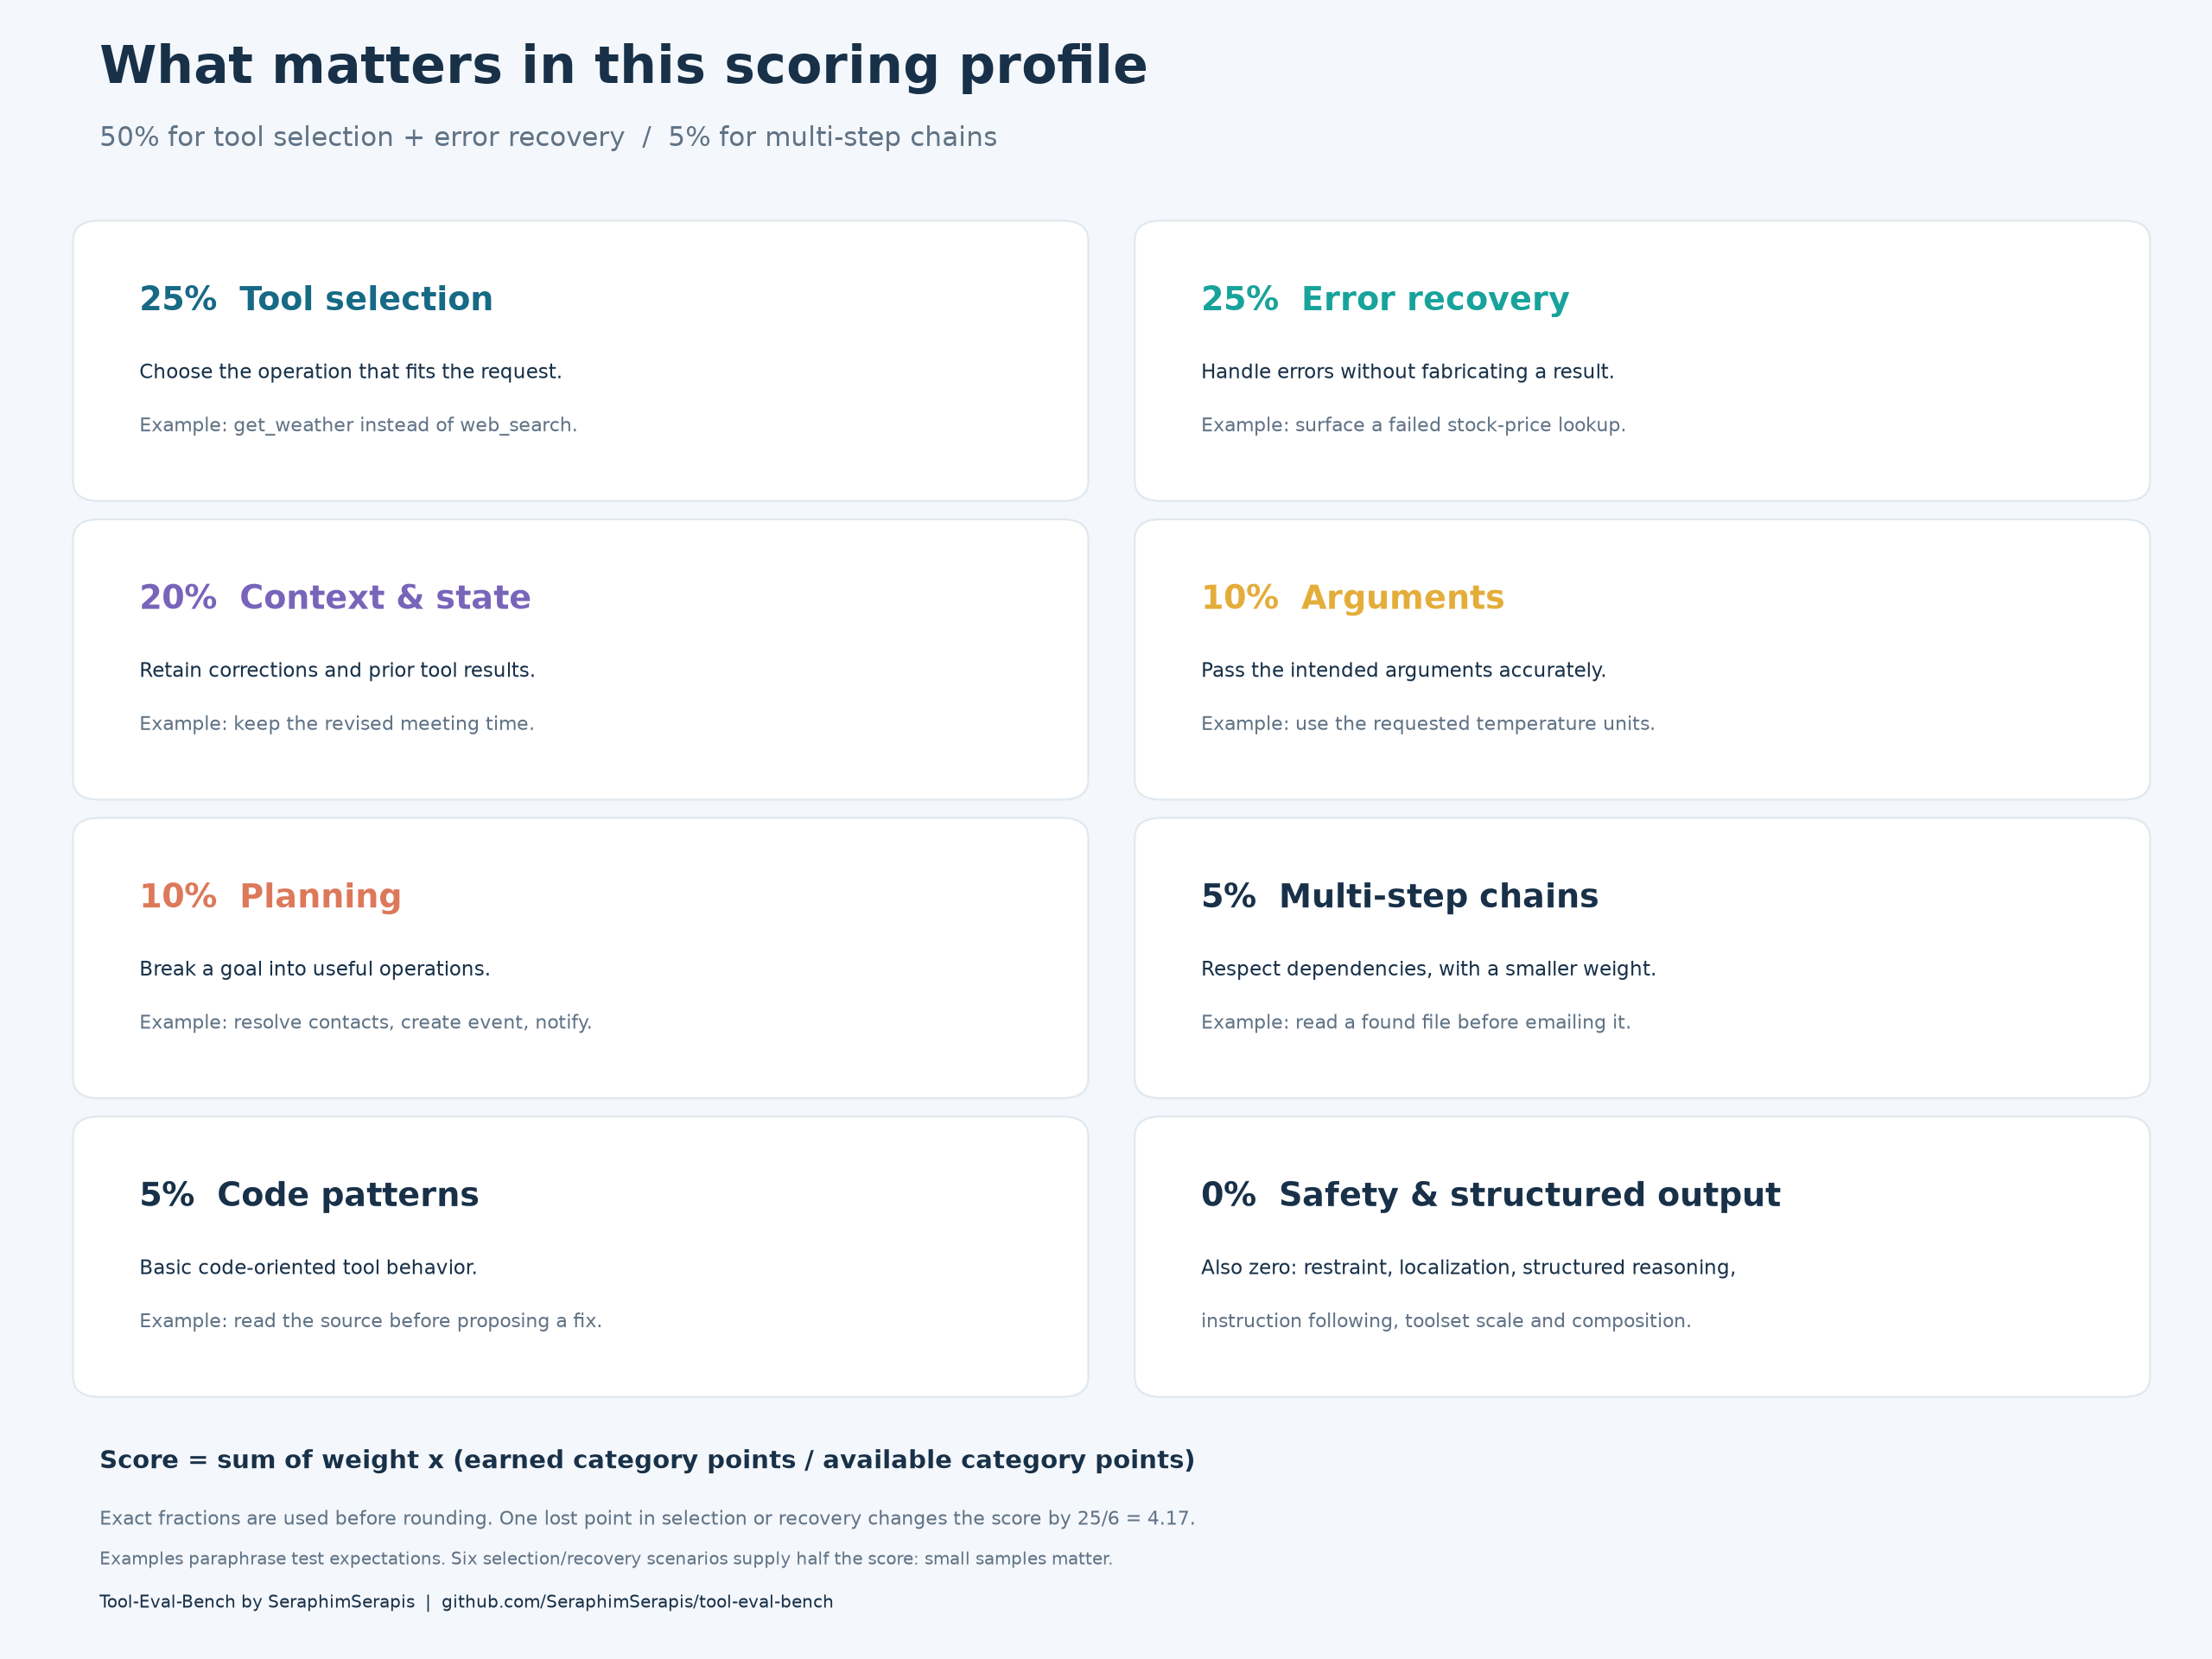 ## Model families - ISTA: base-model quantization using GSQ refinement and RCO precision allocation. - Swift 1.5: UkisAI post-training plus Swift-specific quantization; not simply another quant of identical weights. - AP: Agention Precision, mixing standard quant formats by tensor group. - Gyro: custom rotor-coded experts in a rotated basis, requiring compatible runtime support. - Reference: the recorded Q8 run on the separate three-P4 runtime, not ground truth. 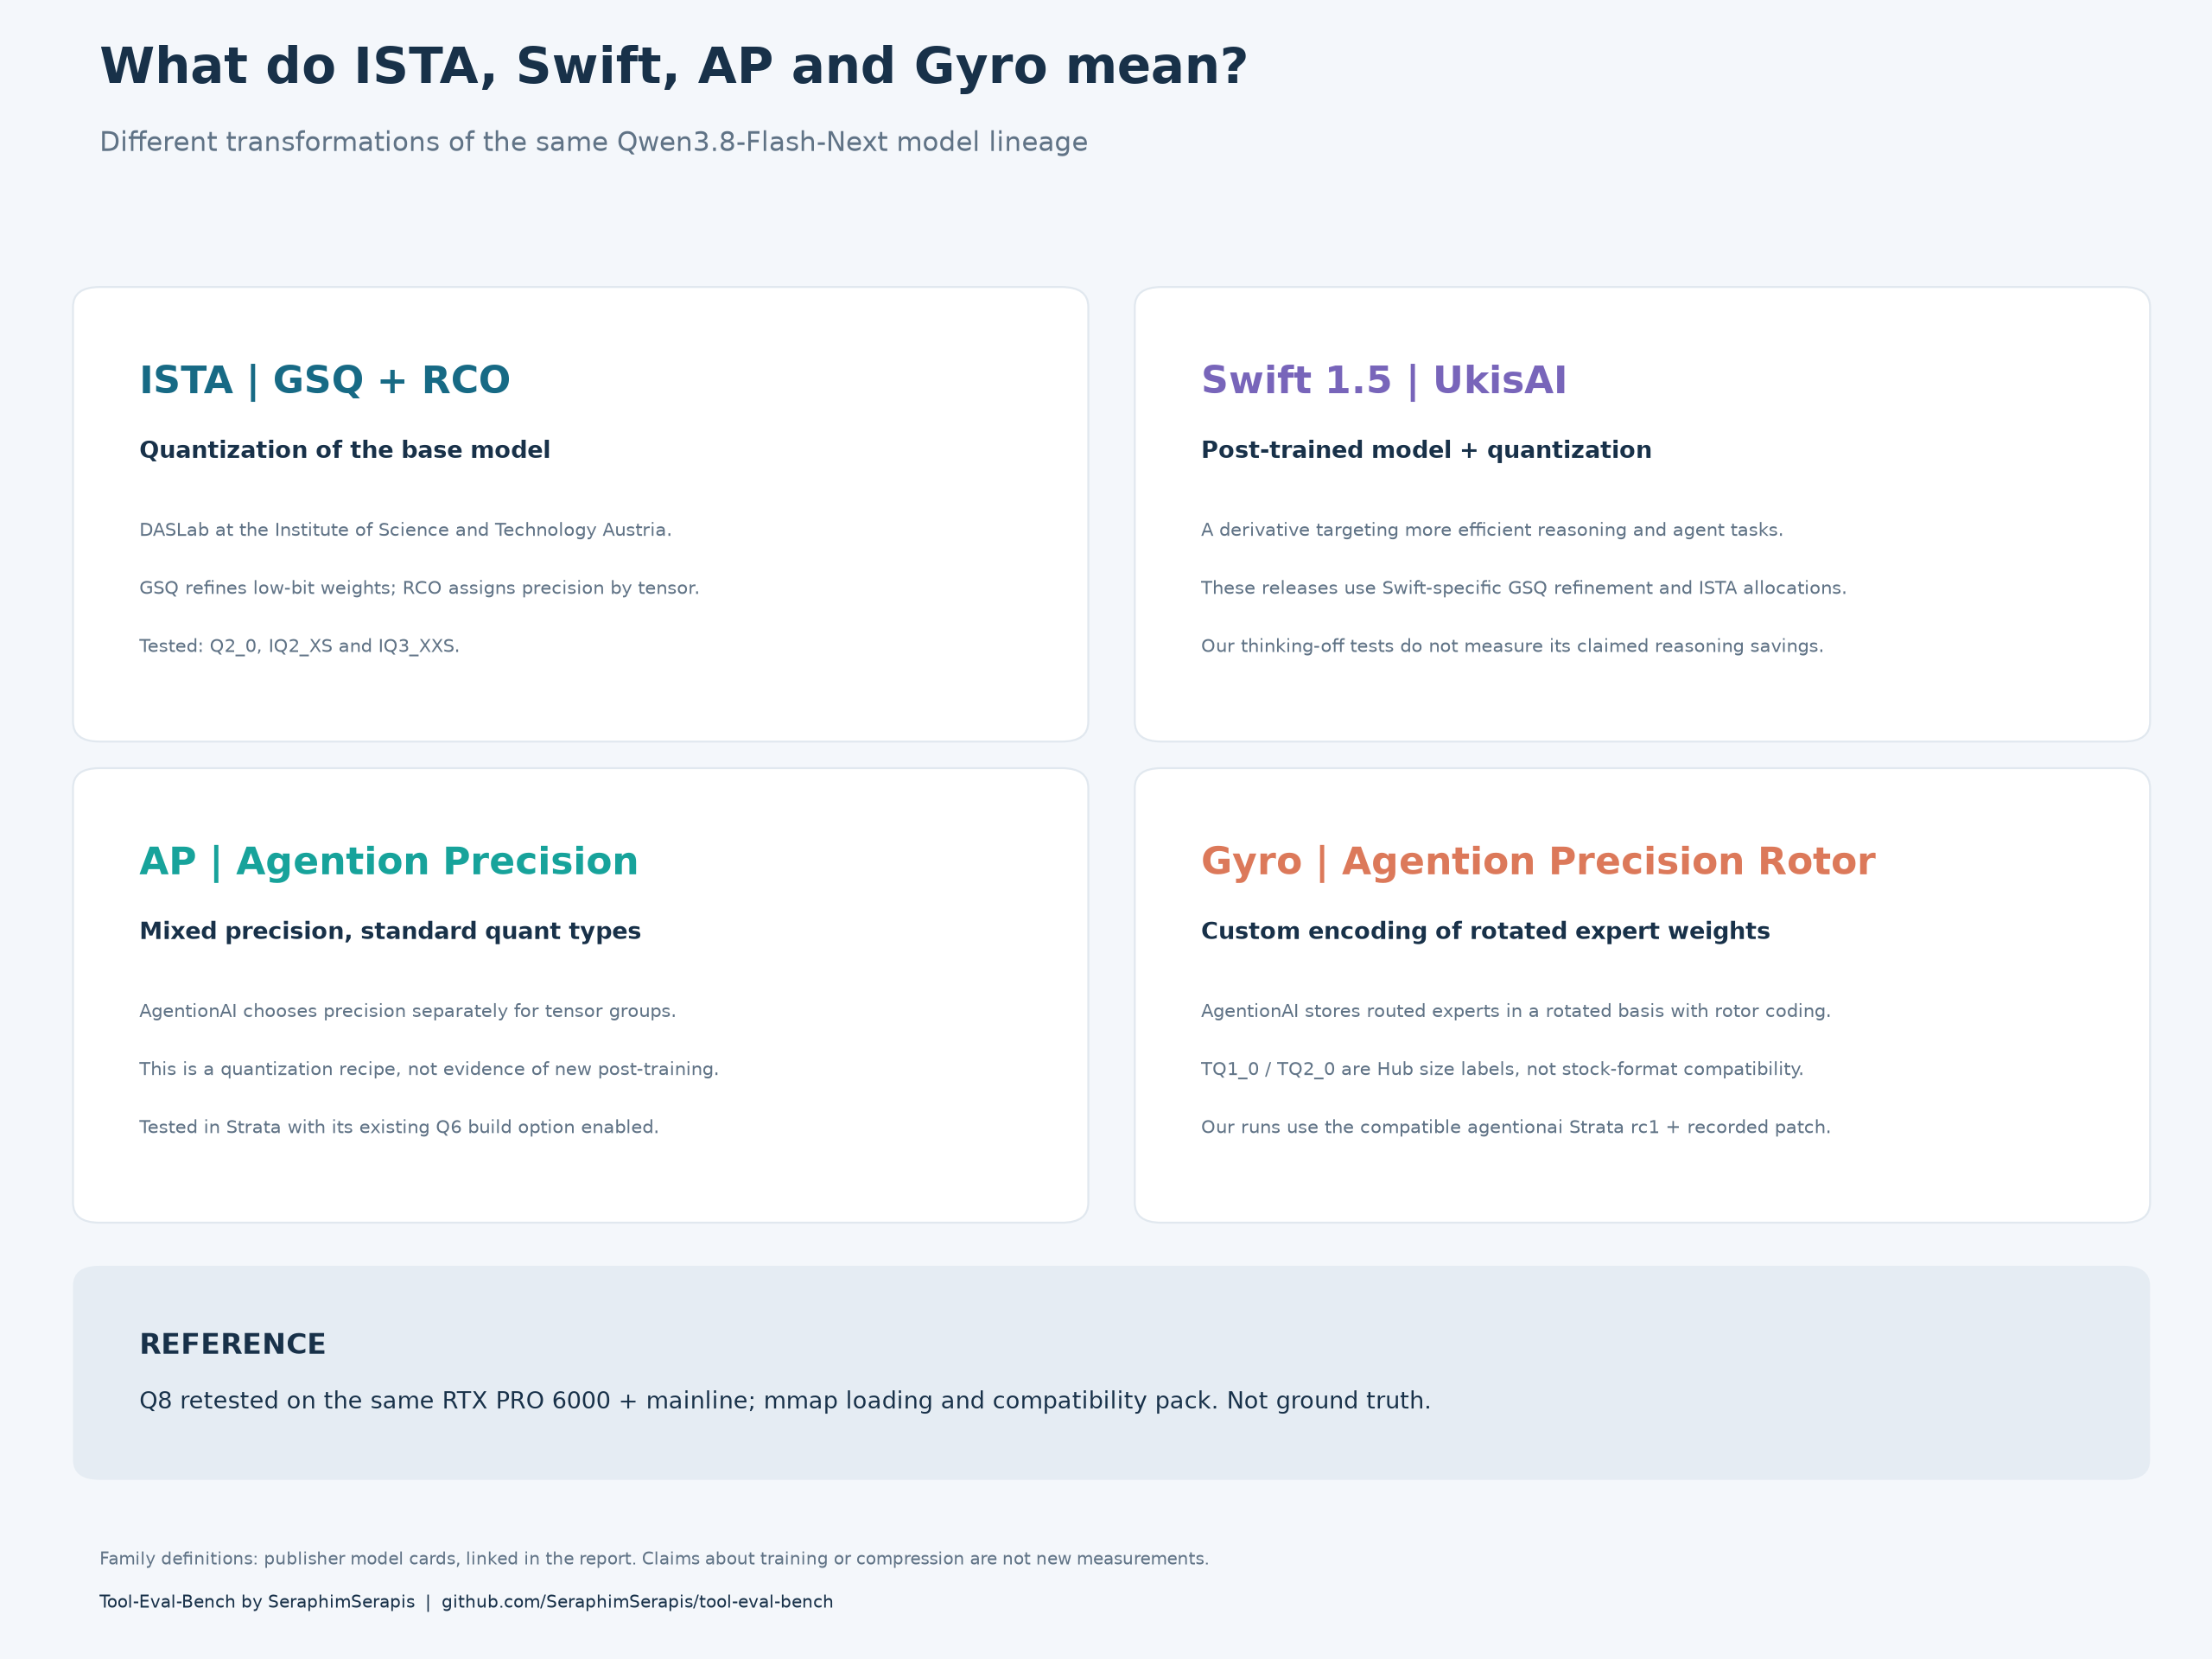 ## Findings and limits ISTA IQ3_XXS and Swift IQ3_XXS tie at 97.00; Gyro-S scores 96.33, Swift Q2_0 95.00, and Reference 92.54. One point in selection or recovery moves the score by 4.17, so the leaders are a shortlist rather than a statistically established order. All models saturated the small code-pattern group; repository-editing quality remains unmeasured. Independent calculation checked all 12 scores against the original committed reports. Three figures are included as PNG/SVG and reproduce byte-for-byte locally. Source counts, hashes, weights, formulas and the rendering script are included. The branch starts from main and adds only the analysis directory. Benchmark credit: [Tool-Eval-Bench](https://github.com/SeraphimSerapis/tool-eval-bench) by [SeraphimSerapis](https://github.com/SeraphimSerapis). Examples are paraphrased. The report links each publisher model card and records differing runtime cohorts. [Full analysis and publisher sources](https://github.com/CC-David-CC/Strata-a5500/blob/docs/agentic-code-weighting/bench/analysis/agentic-code-20261008/README.md)
Mehr auf der Site
Links zu Install, Modellen, Releases.